---
updatedAt: 2026-09-25T21:30:29.000Z
agentTools:
projectIndex: https://docs.getmontecarlo.com/llms.txt
---
# Databricks
# Overview
This guide explains how to set up a Databricks integration with Monte Carlo.
[Databricks](https://docs.databricks.com/en/introduction/index.html) is a data intelligence platform for building, deploying, sharing, and maintaining data, analytics, and AI. It integrates with cloud storage and security in your cloud account, and manages and deploys cloud infrastructure on your behalf.
Monte Carlo connects to Databricks through SQL Warehouses. It collects metadata for catalogs, schemas, tables, and columns, reads Databricks system tables for lineage, query logs, and workflows, and runs your monitors as SQL queries. Monte Carlo supports Databricks on AWS, Azure, and GCP.
### Databricks SQL Warehouses requirement
Databricks offers SQL Warehouses only in the Premium and Enterprise tiers. The Standard tier **is not supported**.
### Databricks Partner Connect
You can also connect to Monte Carlo through Databricks Partner Connect. Create the SQL Warehouse for metadata collection ([Step 3](#step-3-create-sql-warehouses)), then follow the [Partner Connect instructions](https://docs.databricks.com/en/partners/data-governance/monte-carlo.html). Afterwards, return to this guide and complete [Step 2](#step-2-grant-permissions) to grant access to system tables for lineage, query logs, and workflows.
# Feature Support
| Category | Monitor / Lineage Capabilities | Support |
| :----------------- | :---------------------------------------------- | :------ |
| Table Monitor | Freshness | ✅\* |
| Table Monitor | Volume | ✅\* |
| Table Monitor | Schema Changes | ✅ |
| Table Monitor | JSON Schema Changes | ❌ |
| Metric Monitor | Metric | ✅ |
| Metric Monitor | Comparison | ✅ |
| Validation Monitor | Custom SQL | ✅ |
| Validation Monitor | Validation | ✅ |
| Job Monitor | Query performance | ✅\*\* |
| Lineage | Table and column lineage | ✅\*\* |
| Jobs | Databricks Workflows (job runs, failure alerts) | ✅ |
\*Freshness and volume are available for Delta tables, streaming tables, and Unity Catalog external tables. Volume is measured in bytes by default; you can opt in to row count monitoring per table. See [Step 7](#step-7-configure-monitors).
\*\*Requires Unity Catalog. Query logs and query performance cover the queries Databricks records in `system.query.history`.
[More information on monitors in Monte Carlo](https://docs.getmontecarlo.com/docs/monitors-overview).
# Prerequisites
## Permissions
Monte Carlo authenticates to Databricks as a service principal (recommended) or a user with a personal access token. The table below summarizes the access it needs; [Step 2](#step-2-grant-permissions) has the exact grants.
| Area | Permission | Purpose | Required? |
| :------------------------------------ | :-------------------------------------------------------------------------------------------------------------------------------------- | :---------------------------------------------------------------------------------- | :---------- |
| Catalogs | `USE CATALOG`, `USE SCHEMA`, `SELECT` (Unity Catalog) or `USAGE`, `READ_METADATA`, `SELECT` (Hive metastore) on each catalog to monitor | Collect metadata and run monitors | Required |
| SQL Warehouses | **Can use** on both SQL Warehouses | Run metadata collection and monitor queries | Required |
| System tables | `SELECT` on `system.access`, `system.query`, and `system.lakeflow` tables | Lineage, query logs, and Databricks Workflows | Recommended |
| `databricks_pii_access` group | Membership for the Monte Carlo principal | Read query text in `system.query.history`, which Databricks masks for everyone else | Recommended |
| Warehouse cost tables | `SELECT` on `system.billing` and `system.compute` tables | Track the cost of the SQL Warehouses Monte Carlo uses | Optional |
| [Foreign catalogs](#foreign-catalogs) | `USE CATALOG`, `USE SCHEMA`, `SELECT` on each foreign catalog to monitor; `USE CONNECTION` on its connection | Collect and monitor Lakehouse Federation tables | Optional |
| [Delta Shares](#delta-shares) | `USE SHARE` (provider) and `USE PROVIDER` (recipient) on the metastore | Link shared tables to their source across the share | Optional |
**Notes / Recommendations**
* We recommend creating a dedicated service principal for Monte Carlo rather than using personal credentials.
* To limit which catalogs, schemas, or tables Monte Carlo collects, see [Configure ingestion](https://docs.getmontecarlo.com/docs/usage-management#configure-ingestion).
* If your workspace is behind an IP access list or private network, ensure Monte Carlo can reach it. See [IP Allowlisting](https://docs.getmontecarlo.com/docs/networking#ip-allowlisting) for the IP addresses to allow for your deployment.
* To connect over a private network, see [AWS PrivateLink](https://docs.getmontecarlo.com/docs/aws-private-link) or [Azure Private Link](https://docs.getmontecarlo.com/docs/azure-private-link). With Azure Private Link, use the Workspace URL Monte Carlo provides, and note that Partner Connect can't be used.
# Installation
This section guides you through connecting a Databricks workspace to Monte Carlo. Repeat these steps for each workspace you want to monitor.
### Prerequisites
Before proceeding, ensure you have:
* A Monte Carlo account with permissions to add integrations
* Databricks account admin access (to create a service principal) and workspace admin access (to create SQL Warehouses and grant permissions)
* A Databricks workspace on the Premium or Enterprise tier
## Step 1: Create a service principal
When using a service principal, Monte Carlo supports token-based authentication and OAuth machine-to-machine (M2M) authentication. A personal access token is also supported, but not recommended.
### Option 1: Databricks-managed service principal (recommended)
1. As a **Databricks account admin**, log in to the Databricks Account Console, click **User Management**, and open the [Service Principals](https://accounts.cloud.databricks.com/users/serviceprincipals) tab.
2. Click **Add service principal**, enter a **Name** for the service principal, and click **Add**.
3. Ensure that the service principal has the **Databricks SQL access** and **Workspace access** entitlements.
4. Create credentials for the service principal:
* **OAuth (M2M):** follow the [Databricks documentation](https://docs.databricks.com/en/dev-tools/auth/oauth-m2m.html#step-3-create-an-oauth-secret-for-a-service-principal) to create an OAuth secret. Save the **Client ID** and **Secret**.
* **Token:** follow the [Databricks documentation](https://docs.databricks.com/en/dev-tools/service-principals.html#step-4-generate-a-databricks-personal-access-token-for-the-databricks-service-principal) to create a token for the service principal (requires the Databricks APIs). Save the **Token**.
### Option 2: Microsoft Entra ID managed service principal (Azure only)
In the Microsoft Entra admin center:
1. Follow the [Microsoft documentation](https://learn.microsoft.com/en-us/azure/databricks/admin/users-groups/service-principals#databricks-and-microsoft-entra-id-service-principals) to create a Microsoft Entra ID managed service principal. Save the **Application (client) ID** and **Directory (tenant) ID**.
2. Click **Certificates & secrets** in the service principal app and create a secret. Save the secret value.
In Microsoft Azure:
1. Find your Azure Databricks service.
2. Find the **Azure Workspace Resource ID** under **Settings** → **Properties** → **Essentials** → **Id**. It has the format `/subscriptions//resourceGroups//providers/Microsoft.Databricks/workspaces/`.
In Databricks:
1. As a **Databricks account admin**, log in to the Databricks Account Console, click **User Management**, and open the [Service Principals](https://accounts.cloud.databricks.com/users/serviceprincipals) tab.
2. Click **Add service principal**, under **Management** choose **Microsoft Entra ID managed**, and paste the application (client) ID. Enter a **Name** for the service principal, and click **Add**.
3. Ensure that the service principal has the **Databricks SQL access** and **Workspace access** entitlements.
Entra ID managed service principals can only be added to Monte Carlo with the [CLI](#cli).
### Option 3: Personal access token (not recommended)
1. In your Databricks workspace, click your username in the top bar, and then select **Settings**.
2. Under **Developer** → **Access tokens**, click **Generate new token**.
3. Enter a comment that helps you identify this token in the future (for example, `monte-carlo`), and leave the **Lifetime (days)** box empty to create a token with no expiration. Click **Generate**.
4. Copy and save the displayed **Token**, and then click **Done**.
## Step 2: Grant permissions
Configure permissions for each type of catalog in the workspace. If the workspace has both Unity Catalog and Hive metastore catalogs, configure both.
### Unity Catalog
Grant the service principal read access to each catalog you want to monitor. The grants cascade to all schemas within:
```sql
GRANT USE CATALOG ON CATALOG TO ;
GRANT USE SCHEMA ON CATALOG TO ;
GRANT SELECT ON CATALOG TO ;
```
For details, see the [Databricks documentation](https://docs.databricks.com/en/data-governance/unity-catalog/manage-privileges/index.html). If a command returns a "Privilege SELECT is not applicable" error, see [Troubleshooting & FAQ: Databricks](https://docs.getmontecarlo.com/docs/databricks-troubleshooting-faq).
### System tables
Monte Carlo reads Databricks system tables to collect lineage, query logs, and Databricks Workflows jobs and tasks.
1. Follow the Databricks documentation to [enable system tables](https://docs.databricks.com/administration-guide/system-tables/index.html#enable-system-tables) for each workspace that uses Unity Catalog.
2. Grant the service principal access to the system tables:
```sql
GRANT USE CATALOG ON CATALOG system TO ;
GRANT USE SCHEMA ON SCHEMA system.access TO ;
GRANT USE SCHEMA ON SCHEMA system.query TO ;
GRANT USE SCHEMA ON SCHEMA system.lakeflow TO ;
GRANT SELECT ON system.access.table_lineage TO ;
GRANT SELECT ON system.access.column_lineage TO ;
GRANT SELECT ON system.query.history TO ;
GRANT SELECT ON system.lakeflow.jobs TO ;
GRANT SELECT ON system.lakeflow.job_tasks TO ;
GRANT SELECT ON system.lakeflow.job_run_timeline TO ;
GRANT SELECT ON system.lakeflow.job_task_run_timeline TO ;
```
### Query text access
Databricks masks the query text in `system.query.history` for anyone outside the `databricks_pii_access` group. Without query text, the following Monte Carlo features might not work:
* Query performance monitors and query performance anomaly alerts
* Query Insights and the **Performance** page
* Field usage and column popularity
* Table activity (read and write counts, queried-tables detection)
* Impact Analysis users on incidents
* The **Query Log Details** drawer
* The **Discover Queries** widget
* AI monitor recommendations that depend on query patterns
To grant access:
1. Identify the service principal Monte Carlo uses. You can find it in **Settings** → **Integrations** → **Databricks**, in the connection's service principal field. If you have more than one Databricks integration, repeat these steps for each one.
2. In your Databricks account, create the `databricks_pii_access` group if it doesn't exist, and add the Monte Carlo service principal to it. See the [Databricks documentation on managing groups](https://docs.databricks.com/aws/en/admin/users-groups/manage-groups).
3. Verify the membership by running the following as an account admin:
```sql
SELECT *
FROM system.information_schema.group_members
WHERE member_name = '';
```
To apply additional filtering in Monte Carlo, see [PII filtering](https://docs.getmontecarlo.com/docs/pii-filtering).
### Warehouse cost tables (optional)
Monte Carlo can track the compute cost of the SQL Warehouses it uses (metadata collection and query engine), based on Databricks billing system tables. To enable this, enable the `billing` and `compute` system schemas and grant:
```sql
GRANT USE SCHEMA ON SCHEMA system.billing TO ;
GRANT USE SCHEMA ON SCHEMA system.compute TO ;
GRANT SELECT ON system.billing.usage TO ;
GRANT SELECT ON system.billing.list_prices TO ;
GRANT SELECT ON system.compute.warehouses TO ;
GRANT SELECT ON system.compute.warehouse_events TO ;
```
Without these grants, all other features work as usual. Cost collection is enabled by default; to turn it off for your account, contact your Monte Carlo account team.
### Hive metastore
Grant the service principal read access to each catalog. The most common scenario is a single catalog, `hive_metastore`. Permissions cascade to all schemas within. In the Hive metastore, the `SELECT` privilege requires `USAGE`:
```sql
GRANT USAGE, READ_METADATA, SELECT ON CATALOG TO ;
```
For details, see the [Databricks documentation](https://docs.databricks.com/en/sql/language-manual/sql-ref-privileges-hms.html).
### Foreign catalogs
### Upcoming change: foreign catalogs will be collected by default
Monte Carlo will soon collect metadata from foreign (Lakehouse Federation) catalogs the same way it collects native and Delta Sharing catalogs today. Any foreign catalog the Monte Carlo service principal can see will be collected.
To collect a foreign table, Monte Carlo needs to read its column metadata, which Databricks fetches from the external source. If the service principal can see a foreign catalog but lacks access to its columns, collection fails, while listing the catalog's schemas and tables still uses SQL Warehouse compute.
Decide for each foreign catalog:
* **To monitor it:** grant access all the way down to the column level:
```sql
GRANT USE CATALOG ON CATALOG TO ;
GRANT USE SCHEMA ON CATALOG TO ;
GRANT SELECT ON CATALOG TO ;
```
Optionally, also grant `USE CONNECTION` on the underlying connection so Monte Carlo can match federated tables to their source:
```sql
GRANT USE CONNECTION ON CONNECTION TO ;
```
* **To skip it:** either revoke the service principal's access to the catalog, or add an exclusion rule in [Configure ingestion](https://docs.getmontecarlo.com/docs/usage-management#configure-ingestion). Otherwise, Monte Carlo keeps trying to collect it and spending SQL Warehouse compute with nothing to show for it.
### Delta Shares
If you use Delta Sharing, you can grant additional permissions on both sides of the share (provider and recipient). This lets Monte Carlo link shared tables to their source tables across the share.
* On the provider side (the workspace that hosts the shared data):
```sql
GRANT USE SHARE ON METASTORE TO ;
```
* On the recipient side (the workspace that references the shared data):
```sql
GRANT USE PROVIDER ON METASTORE TO ;
```
⚠️ Linking only works if both the provider and the recipient workspaces are connected to the same Monte Carlo account.
## Step 3: Create SQL Warehouses
Monte Carlo uses two connections, each backed by a SQL Warehouse:
* **Metadata collection:** collects table metadata, query logs, lineage, Databricks Workflows, and row counts for opt-in volume monitors. Consists of many small metadata queries.
* **Query engine:** runs monitors and root-cause analysis queries. Needs to scale with the number and frequency of monitors and the data size.
You can use the same SQL Warehouse for both, but we recommend a separate one for each.
Follow the [Databricks documentation](https://docs.databricks.com/sql/admin/sql-endpoints.html#create-a-sql-warehouse) to create each SQL Warehouse with these settings:
| Setting | Metadata collection | Query engine |
| :----------------- | :----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | :------------------------------------------------------------------------------ |
| Type | `Serverless` (recommended) or `Pro`. For an external Hive metastore, only `Pro` is supported. `Classic` is not supported. | `Serverless` (recommended) or `Pro`. `Classic` is not supported. |
| Size | `2X-Small` for up to 10,000 tables. Larger environments, or many large Delta tables, may need more. | Start with `2X-Small` and scale as needed. |
| Auto stop | As short as possible: 1 minute for Serverless (API only), 10 minutes for Pro. See [How can I reduce the cost of the Databricks integration?](#how-can-i-reduce-the-cost-of-the-databricks-integration) | As short as possible: 1 minute for Serverless (API only), 10 minutes for Pro. |
| Min / max clusters | 1 / 1. Autoscaling can cause performance problems for metadata collection. | 1 / 1. Enable autoscaling only if monitor load spikes at specific times of day. |
| Permissions | Grant the service principal (or user) **Can use** | Grant the service principal (or user) **Can use** |
To grant **Can use**, click **Permissions** at the top right of the SQL Warehouse configuration page and add the service principal. Save each **Warehouse ID** and start both SQL Warehouses. Reach out to your account representative for help right-sizing.
## Step 4: Verify data access
Confirm that the SQL Warehouse can access the catalogs, schemas, and tables you want to monitor. Run the following in the Databricks SQL editor:
```sql
SHOW CATALOGS;
SHOW SCHEMAS IN ;
SHOW TABLES IN ;
DESCRIBE EXTENDED ;
```
If the commands don't show the objects you expect, check the permissions and the SQL Warehouse settings, and make sure the SQL Warehouse connects to the correct metastore. Note that these commands run as your own user; results can differ for the Monte Carlo service principal.
## Step 5: Gather connection information
| Field | Description | Where to find |
| :------------------------------------------ | :-------------------------------------------------------- | :----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Workspace URL** | Full URL of your workspace | Your browser address bar, for example `https://dbc-12345678-abcd.cloud.databricks.com`. Include `https://`. |
| **Workspace ID** | Numeric ID of your workspace | The number after `o=` in the workspace URL. For example, in `https:///?o=6280049833385130` the ID is `6280049833385130`. If there is no `o=` in the URL, the workspace ID is `0`. |
| **Metadata Warehouse ID** | ID of the metadata collection SQL Warehouse | [Step 3](#step-3-create-sql-warehouses) |
| **Query engine Warehouse ID** | ID of the query engine SQL Warehouse | [Step 3](#step-3-create-sql-warehouses) |
| **Token** | Service principal token or personal access token | [Step 1](#step-1-create-a-service-principal) (token authentication) |
| **Client ID** and **Client Secret** | OAuth credentials of the service principal | [Step 1](#step-1-create-a-service-principal) (OAuth authentication) |
| **Tenant ID** and **Workspace Resource ID** | Azure identifiers for Entra ID managed service principals | [Step 1, Option 2](#option-2-microsoft-entra-id-managed-service-principal-azure-only) |
## Step 6: Add the Databricks integration in Monte Carlo
You can add the Databricks integration using the Monte Carlo UI or CLI. Make sure both SQL Warehouses are running before you start.
### UI
This step uses the Monte Carlo UI to add the Connections.
1. To add the Connections, navigate to the [Integrations](https://getmontecarlo.com/settings/integrations) page in Monte Carlo. If this page is not visible to you, please reach out to your account representative.
2. Under the **Data Lake and Warehouses** section, click the **Create** button and **Databricks**.
3. Use the **Create Databricks metadata collection and querying connections** button.
4. Under **Warehouse Name**, enter the name of the connection that you would like to see in Monte Carlo for this Databricks Workspace.
5. Under **Workspace URL**, enter the full URL of your Workspace, i.e. `https://${instance_id}.cloud.databricks.com`. Be sure to enter the `https://`.
6. Under **Workspace ID**, enter the Workspace ID of your Databricks Workspace. If there is `o=` in your Databricks Workspace URL, for example, `https:///?o=6280049833385130`, the number after `o=` is the Databricks Workspace ID. Here the workspace ID is `6280049833385130`. If there is no `o=` in the deployment URL, the workspace ID is `0`.
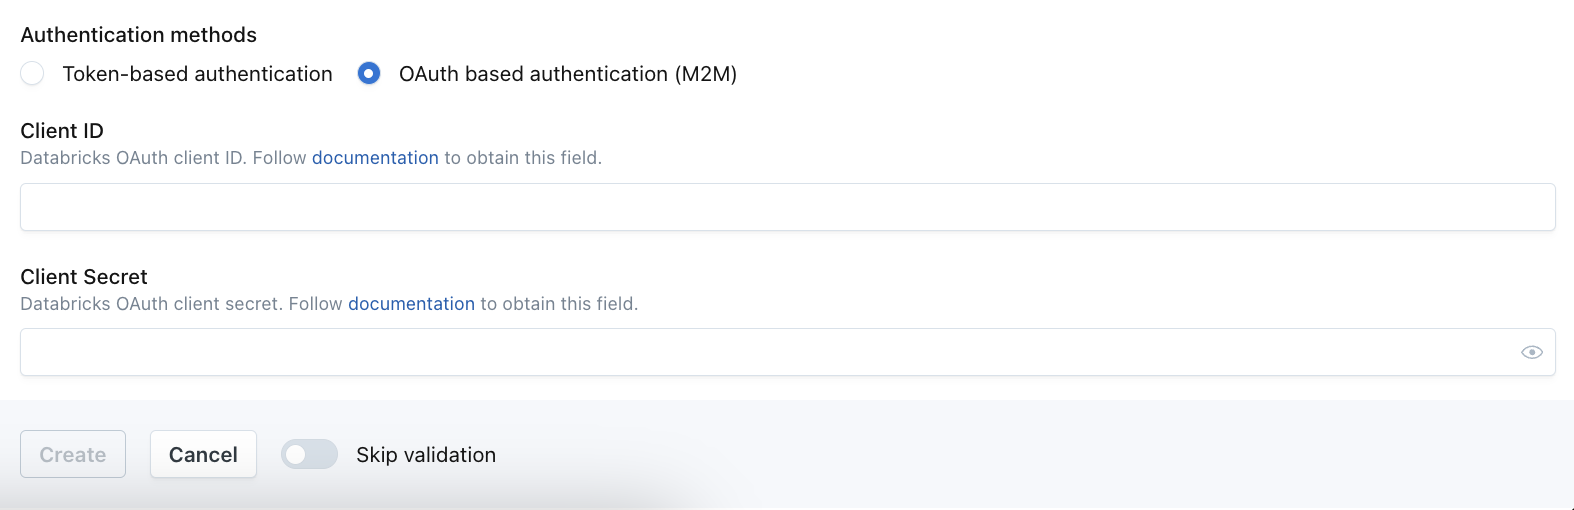
7. Under **Authentication methods**, enter the Service Principal or Personal Access Token, or the OAuth Client ID and Client Secret, you created in [Step 1](https://docs.getmontecarlo.com/docs/overview-databricks#step-1-create-a-service-principal).
8. For Metadata Collection Jobs, enter the **SQL Warehouse ID** of the metadata collection SQL Warehouse ([Step 3](https://docs.getmontecarlo.com/docs/overview-databricks#step-3-create-sql-warehouses)).
9. Under Query Engine, select the integration type that matches what you set up in Step 3 and enter the **SQL Warehouse ID** of the query engine SQL Warehouse ([Step 3](https://docs.getmontecarlo.com/docs/overview-databricks#step-3-create-sql-warehouses)).
10. Click **Create** and validate that the connection was created successfully.
For OAuth with a Databricks-managed service principal, select **OAuth based authentication** under **Authentication methods**, and enter the **Client ID** and **Client Secret**.
### CLI
### CLI Setup
If you haven't installed the Monte Carlo CLI, follow the [CLI setup guide](https://docs.getmontecarlo.com/docs/using-the-cli) first.
The CLI adds each connection separately: first the metadata collection connection, which creates the integration, then the query engine connection.
#### Metadata collection connection
```shell Command Help
Usage: montecarlo integrations add-databricks-metastore-sql-warehouse
[OPTIONS]
Setup a Databricks metastore sql warehouse integration. For metadata.
Options:
--name TEXT Friendly name for the created integration
(e.g. warehouse). Name must be unique.
--connection-name TEXT Friendly name for the connection.
--databricks-workspace-url TEXT
Databricks workspace URL. [required]
--databricks-token TEXT Databricks access token. If you prefer a
prompt (with hidden input) enter -1.
--databricks-warehouse-id TEXT Databricks warehouse ID. [required]
--databricks-client-id TEXT Databricks OAuth Client ID. This option
cannot be used with 'databricks-token'. This
option requires setting 'databricks-client-
secret'.
--databricks-client-secret TEXT
Databricks OAuth Client Secret. If you
prefer a prompt (with hidden input) enter
-1. This option cannot be used with
'databricks-token'. This option requires
setting 'databricks-client-id'.
--azure-tenant-id TEXT Azure Tenant ID, needed when using an Entra-
ID managed service principal. This option
cannot be used with 'databricks-token'. This
option requires setting 'azure-workspace-
resource-id'.
--azure-workspace-resource-id TEXT
Azure Workspace Resource, needed when using
an Entra-ID managed service principal. This
option cannot be used with 'databricks-
token'. This option requires setting 'azure-
tenant-id'.
--agent-id UUID ID for the agent. To disambiguate accounts
with multiple agents. This option cannot be
used with 'dc-id'.
--collector-id UUID ID for the data collector. To disambiguate
accounts with multiple collectors. This
option cannot be used with 'agent-id'.
--skip-validation Skip all connection tests. This option
cannot be used with 'validate-only'.
--validate-only Run connection tests without adding. This
option cannot be used with 'skip-
validation'.
--auto-yes Skip any interactive approval.
--databricks-workspace-id TEXT Databricks workspace ID. [required]
--option-file FILE Read configuration from FILE.
--help Show this message and exit.
```
**Example (OAuth with a Databricks-managed service principal):**
```bash
montecarlo integrations add-databricks-metastore-sql-warehouse \
--name databricks-prod \
--databricks-workspace-url https://dbc-12345678-abcd.cloud.databricks.com \
--databricks-workspace-id 6280049833385130 \
--databricks-warehouse-id 1234567890abcdef \
--databricks-client-id \
--databricks-client-secret -1
```
For token authentication, replace the client ID and secret with `--databricks-token -1`. For an Entra ID managed service principal, also add `--azure-tenant-id ` and `--azure-workspace-resource-id `.
#### Query engine connection
```shell Command Help
Usage: montecarlo integrations add-databricks-sql-warehouse [OPTIONS]
Setup a Databricks SQL Warehouse integration. For health queries
Options:
--databricks-workspace-url TEXT
Databricks workspace URL. [required]
--databricks-token TEXT Databricks access token. If you prefer a
prompt (with hidden input) enter -1.
--databricks-warehouse-id TEXT Databricks warehouse ID. [required]
--databricks-client-id TEXT Databricks OAuth Client ID. This option
cannot be used with 'databricks-token'. This
option requires setting 'databricks-client-
secret'.
--databricks-client-secret TEXT
Databricks OAuth Client Secret. If you
prefer a prompt (with hidden input) enter
-1. This option cannot be used with
'databricks-token'. This option requires
setting 'databricks-client-id'.
--azure-tenant-id TEXT Azure Tenant ID, needed when using an Entra-
ID managed service principal. This option
cannot be used with 'databricks-token'. This
option requires setting 'azure-workspace-
resource-id'.
--azure-workspace-resource-id TEXT
Azure Workspace Resource, needed when using
an Entra-ID managed service principal. This
option cannot be used with 'databricks-
token'. This option requires setting 'azure-
tenant-id'.
--name TEXT Friendly name of the warehouse which the
connection will belong to.
--connection-name TEXT Friendly name for the connection.
--agent-id UUID ID for the agent. To disambiguate accounts
with multiple agents. This option cannot be
used with 'dc-id'.
--collector-id UUID ID for the data collector. To disambiguate
accounts with multiple collectors. This
option cannot be used with 'agent-id'.
--skip-validation Skip all connection tests. This option
cannot be used with 'validate-only'.
--validate-only Run connection tests without adding. This
option cannot be used with 'skip-
validation'.
--auto-yes Skip any interactive approval.
--option-file FILE Read configuration from FILE.
--help Show this message and exit.
```
**Example:** pass the integration name from the previous command in `--name` to add the query engine connection to the same integration:
```bash
montecarlo integrations add-databricks-sql-warehouse \
--name databricks-prod \
--databricks-workspace-url https://dbc-12345678-abcd.cloud.databricks.com \
--databricks-warehouse-id fedcba0987654321 \
--databricks-client-id \
--databricks-client-secret -1
```
### Add a SQL Warehouse to an existing integration
To add a query engine SQL Warehouse to an existing Databricks integration, either run `add-databricks-sql-warehouse` with the existing integration name in `--name`, or start creating a new Databricks connection on the [Integrations](https://getmontecarlo.com/settings/integrations) page and select **Add to existing integration**.
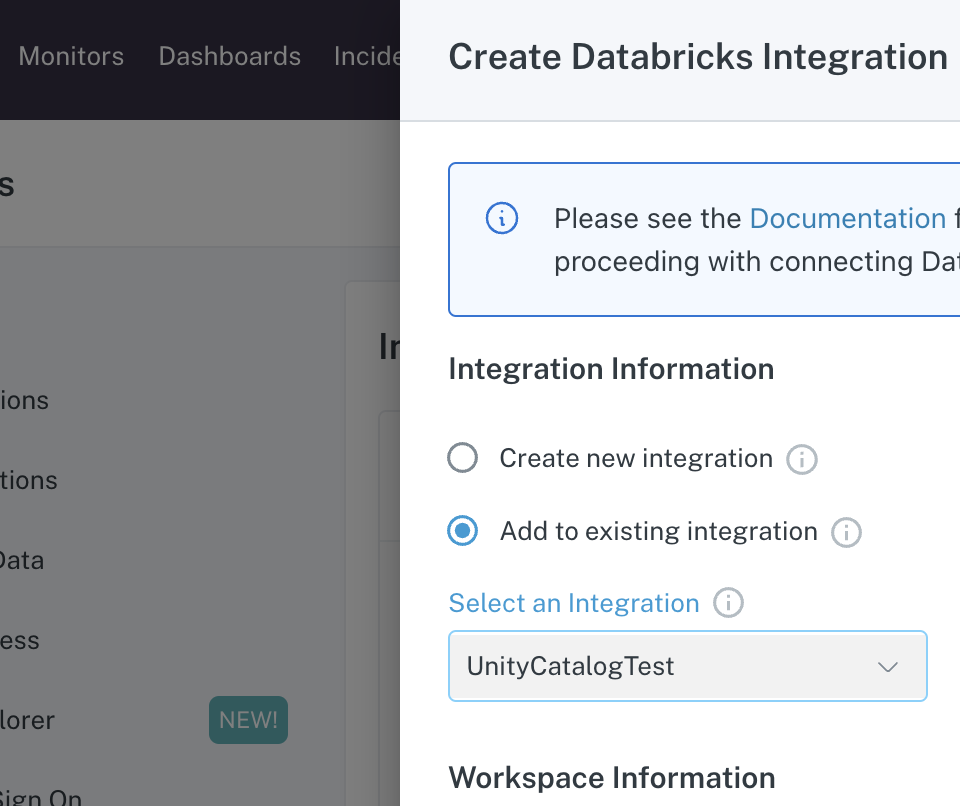
Each SQL Warehouse connection is scoped to the single workspace whose URL you provide. To monitor another workspace, set up a separate Databricks integration for it.
***
After configuring your integration, you can see details, run validations, and delete connections on the [Integrations](https://getmontecarlo.com/settings/integrations) page. To test a connection:
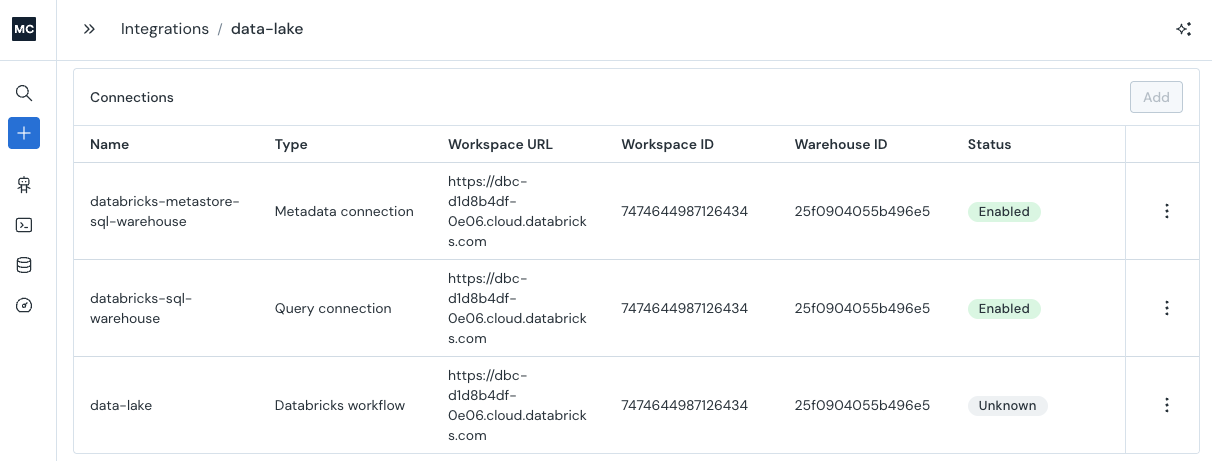
1. Navigate to **Settings** → **Integrations**.
2. Click your Databricks integration.
3. Select the connection you want to test.
4. Click **Test** in the connection menu.
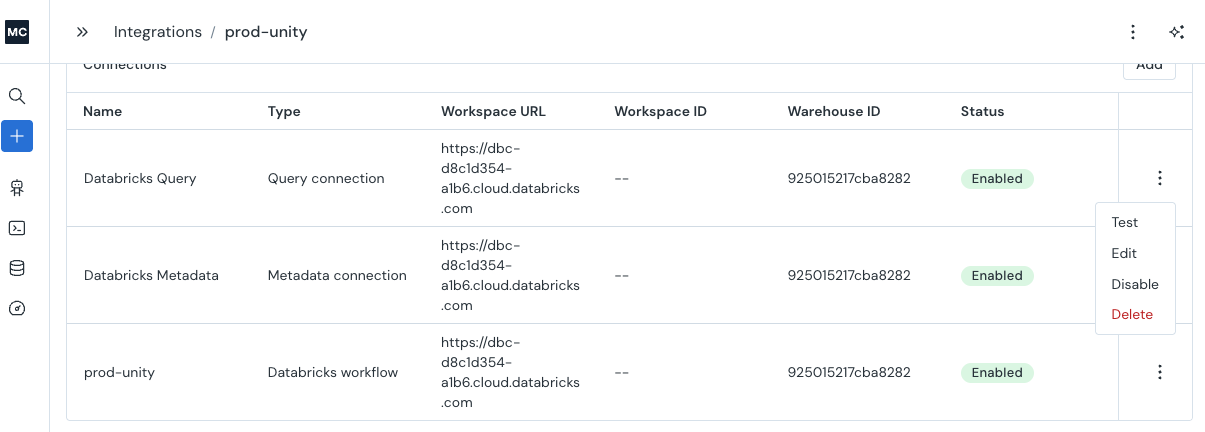
All checks should show green checkmarks. If any check fails, the result includes steps to resolve it.
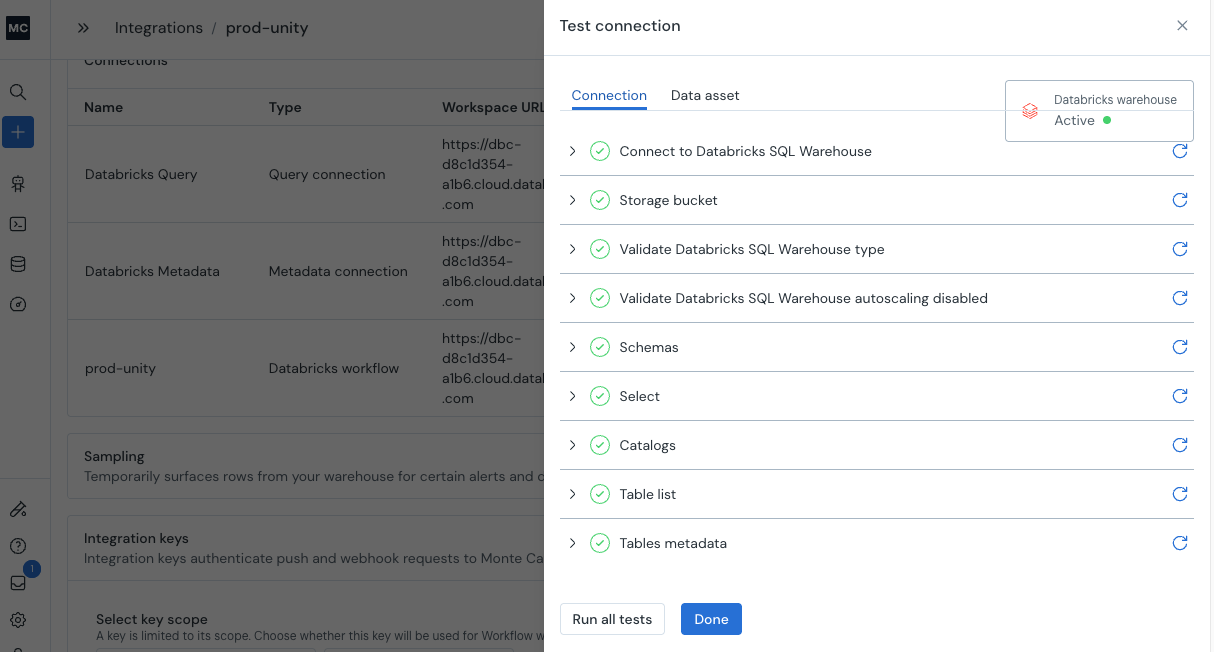
Your Databricks assets appear on the Assets page within a few minutes to an hour. Lineage can take up to 24 hours due to batching.
## Step 7: Configure monitors
For new Databricks integrations, Monte Carlo collects freshness and volume only for tables that have a monitor. To start collecting them for a table, add a monitor on it. Collection starts when the monitor is added, with no earlier history, so anomaly detection needs a short period to establish a baseline before it starts alerting.
To collect freshness and volume for all tables automatically, contact your Monte Carlo account team. A monitor is still required to receive alerts, and you can use [Configure ingestion](https://docs.getmontecarlo.com/docs/usage-management#configure-ingestion) to exclude schemas or tables you don't need.
Volume is measured in bytes by default. To monitor row counts instead, click **Enable row count monitoring** on the Volume tile of the table's page.
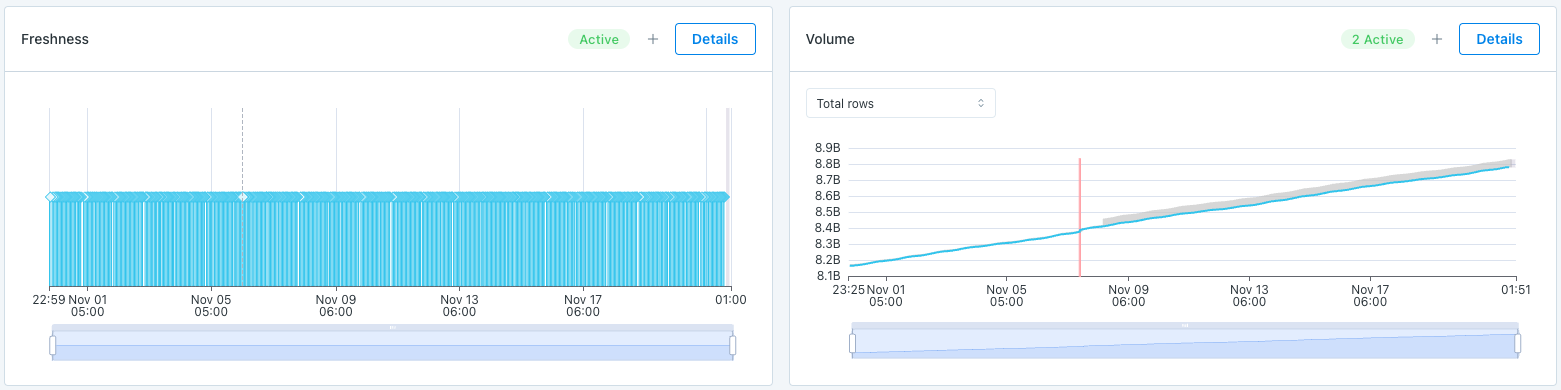
For other monitor types, see [Monitors overview](https://docs.getmontecarlo.com/docs/monitors-overview).
## Step 8: Set up Databricks Workflows alerts (optional)
To receive Databricks Workflows failures as alerts in Monte Carlo, set up a webhook. See [Databricks Workflows](https://docs.getmontecarlo.com/docs/databricks-workflow#2-databricks-workflows-failures-as-mc-alerts).
# FAQs
## What Databricks deployments are supported?
Monte Carlo supports Databricks on AWS, Azure, and GCP, on the Premium and Enterprise tiers. It connects through `Serverless` or `Pro` SQL Warehouses; `Classic` SQL Warehouses and the Standard tier are not supported.
## What authentication methods are supported?
* OAuth (M2M) with a Databricks-managed service principal
* OAuth (M2M) with a Microsoft Entra ID managed service principal (CLI only)
* Service principal token
* Personal access token
## What tables are supported?
Delta tables, Unity Catalog external tables, and streaming tables get freshness and volume monitoring. For other tables, including materialized views, you can use metric, custom SQL, and validation monitors.
## How many workspaces are supported?
Each Databricks integration connects to one workspace. Set up a separate integration for each workspace you want to monitor. With Unity Catalog, a catalog shared by several workspaces only needs to be connected once.
## Does Monte Carlo import Databricks tags?
Yes. Monte Carlo imports Unity Catalog table and column tags with the table metadata. Databricks Workflows job tags are also imported; see [Databricks Workflows](https://docs.getmontecarlo.com/docs/databricks-workflow).
## Why don't I see freshness and volume for all my tables?
New integrations collect freshness and volume only for tables that have a monitor. See [Step 7](#step-7-configure-monitors).
## How can I reduce the cost of the Databricks integration?
Shorten the auto stop on both SQL Warehouses, starting with the one used for metadata collection. Metadata collection runs many short queries spread through the day, so a long auto stop keeps the warehouse running while it is idle.
For a `Serverless` SQL Warehouse, we recommend an auto stop of 1 minute. The Databricks UI does not allow a value below 5 minutes, but the [SQL Warehouses API](https://docs.databricks.com/api/workspace/warehouses/edit) accepts `auto_stop_mins: 1`. For a `Pro` SQL Warehouse, 10 minutes is the lowest value Databricks allows.
## Can I use another query engine instead of a SQL Warehouse?
We recommend a SQL Warehouse as the query engine for Databricks. Other query engines may work; see [Data Lakes](https://docs.getmontecarlo.com/docs/data-lakes).
## Are there any known limitations?
* **Volume** is measured in bytes by default; row count monitoring is opt-in per table.
* **Lineage** requires Unity Catalog.
* **Query logs and query performance** require Unity Catalog, and cover the queries Databricks records in `system.query.history`.
* **JSON schema change** monitoring is not supported.
For troubleshooting, see [Troubleshooting & FAQ: Databricks](https://docs.getmontecarlo.com/docs/databricks-troubleshooting-faq).
# Related guides
* [Databricks Workflows](https://docs.getmontecarlo.com/docs/databricks-workflow): jobs on lineage and as assets, and workflow failures as alerts
* [Databricks External Tables](https://docs.getmontecarlo.com/docs/databricks-external-tables): monitor files in cloud storage through Unity Catalog external tables
* [Databricks agents](https://docs.getmontecarlo.com/docs/databricks-agent-bricks): trace-level Agent Observability for Databricks agents and AI/BI Genie spaces, through the same SQL Warehouse connection