
dbt Integration
Overview
Monte Carlo integrates with dbt to provide run history, model and test failure alerts, and dbt context in lineage for your dbt projects. Monte Carlo imports the artifacts dbt writes for every run (the manifest, run results, and logs), and links each model, test, snapshot, and seed to the table it builds or checks. You can see which dbt job built a table, how its latest runs went, and whether a failed model or test explains an anomaly downstream.
When a dbt model, test, snapshot, or seed fails, Monte Carlo can raise it as an alert, so you get centralized incident triage, notification routing, and reporting across all your data and system issues.
Monte Carlo supports both flavors of dbt:
- dbt Cloud: dbt Cloud calls a Monte Carlo webhook when a job run completes, and Monte Carlo fetches the run's artifacts through the dbt Cloud API.
- dbt Core: your production workflow uploads the artifacts with the Monte Carlo CLI or Python SDK after each dbt command.
Feature Support
| Category | Capability | dbt Cloud | dbt Core |
|---|---|---|---|
| Runs | Job and model run history | ✅ | ✅ |
| Runs | Collection as soon as a run completes | ✅ | ✅ |
| Alerts | Model, test, snapshot, and seed failure alerts | ✅ | ✅ |
| Alerts | Group repetitive failures into one alert | ✅ | ✅ |
| Catalog | dbt descriptions, tags, and meta on tables | ✅ | ✅ |
| Lineage | dbt job and status on table lineage | ✅ | ✅ |
| Lineage | Table-to-table lineage from the dbt manifest | ❌ | ❌ |
| Lineage | Column-level lineage | ❌ | ❌ |
| Performance | Query performance by dbt job and model | ✅ | ✅ |
What Monte Carlo Ingests
For every dbt run, Monte Carlo imports:
manifest.json: your project's models, tests, snapshots, seeds, and sources, with their descriptions, tags, meta, and SQL.run_results.json: the status, timing, and error message of each node in the run.- Logs (optional for dbt Core): the console output of the dbt command.
Monte Carlo organizes this into projects, jobs, and runs:
- In dbt Cloud, projects and jobs are your dbt Cloud projects and jobs.
- In dbt Core, you name the project and job when you upload the artifacts. See Project and Job.
Each model, snapshot, and seed is matched to a table in the warehouse or lake connection the dbt run targets. Tests are attached to the model they test. A node that doesn't match a table in Monte Carlo isn't imported, so make sure that warehouse is connected and the schemas your models write to aren't excluded.
On table pages
dbt model and column descriptions, tags, and meta configs are imported to the matching tables. Model tags can also be imported as asset tags on the parent dbt job with a project-level opt-in in the dbt integration settings. See Asset tags → dbt Tags.
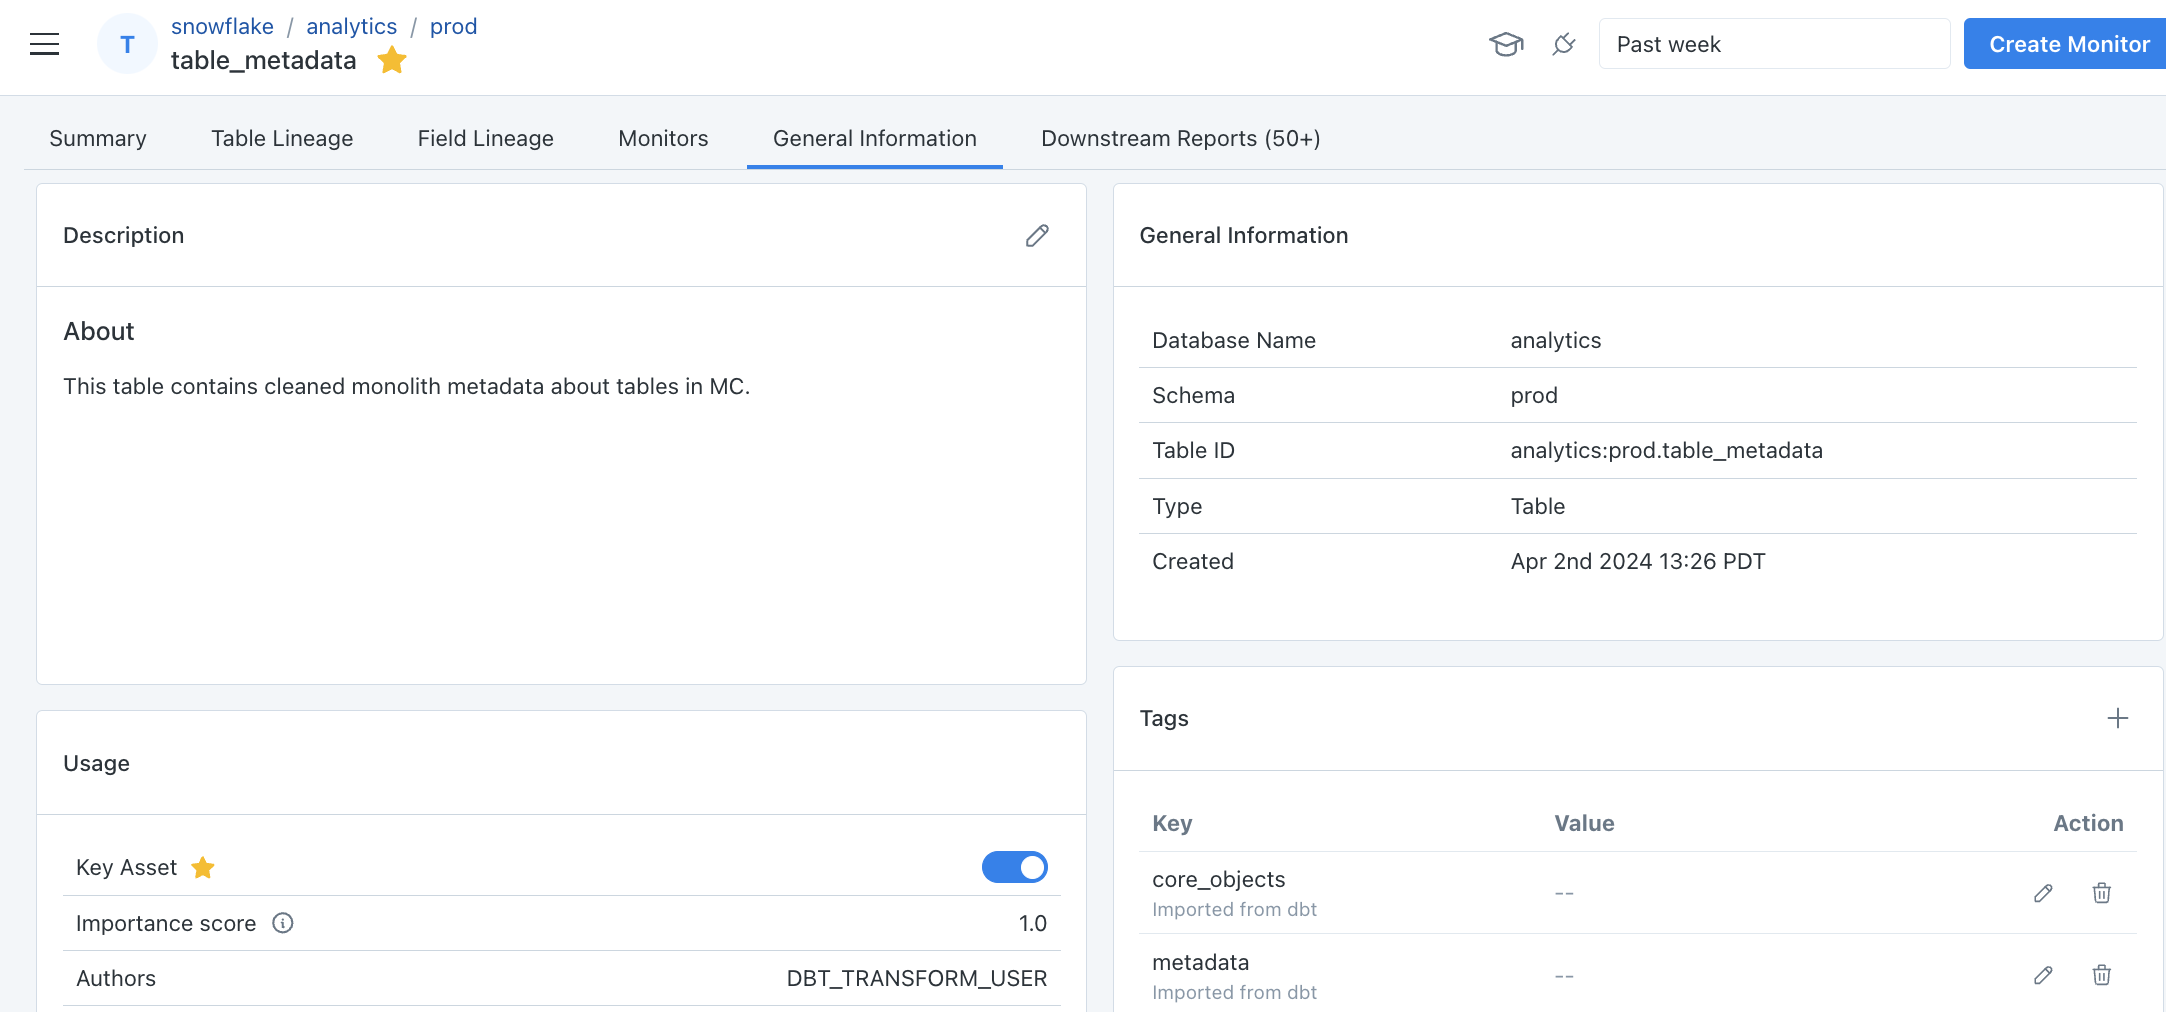
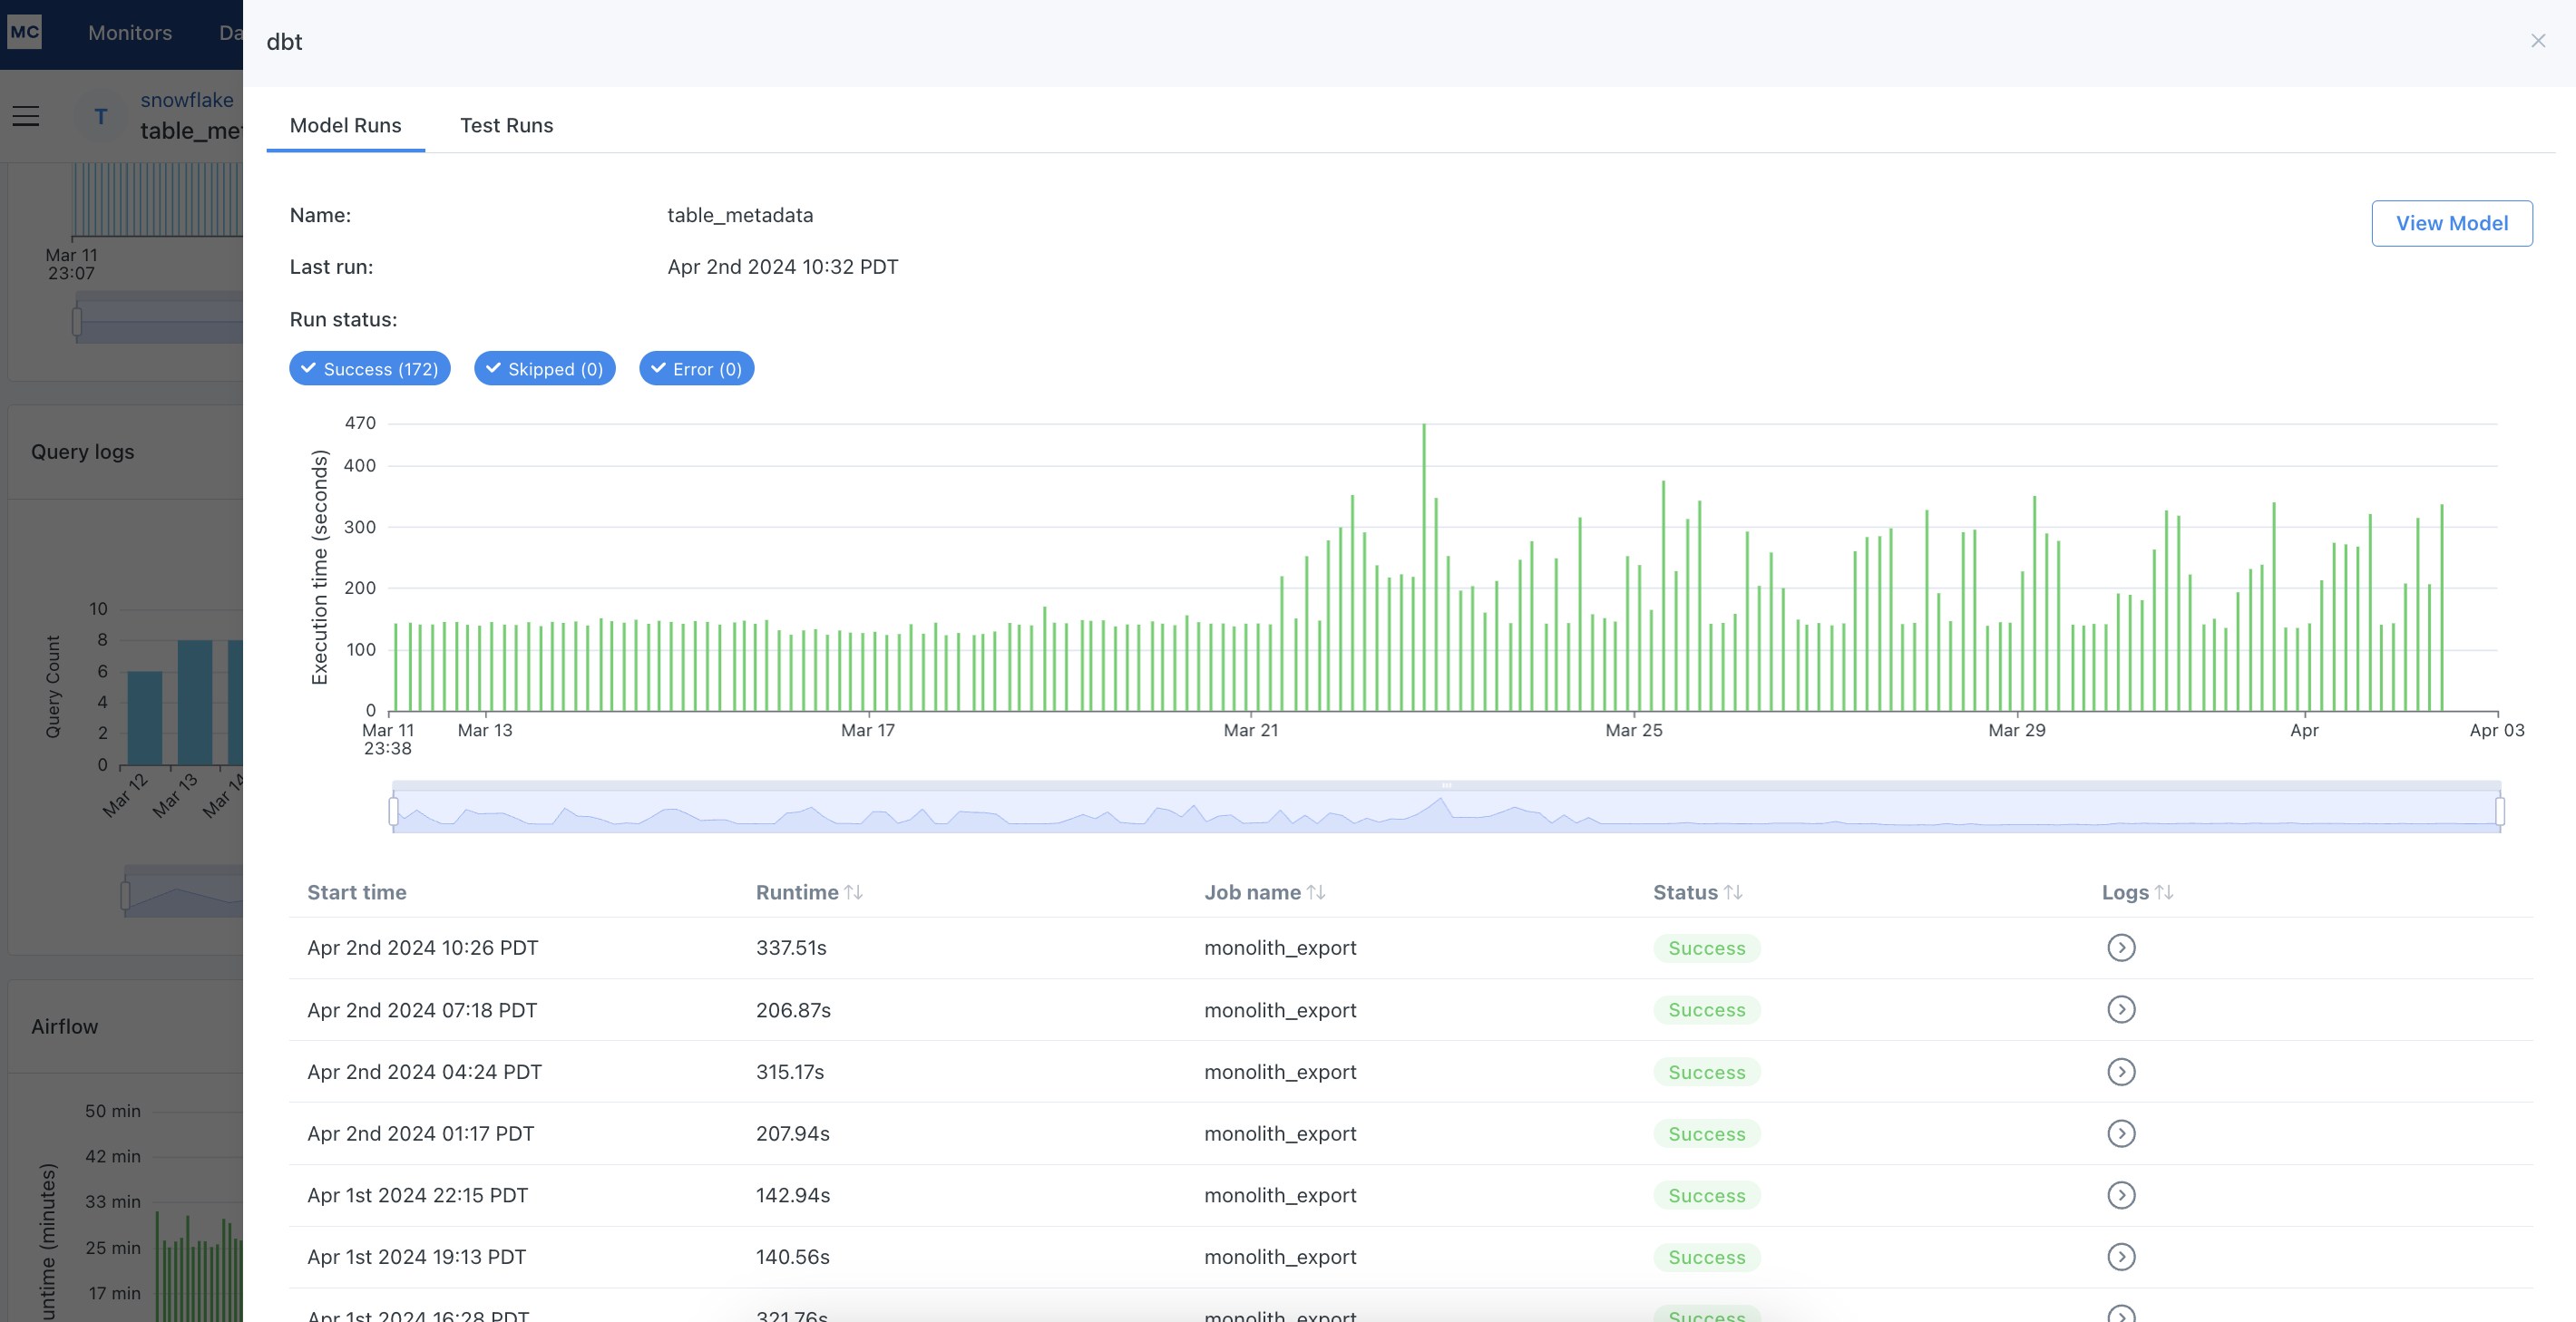
A table built by dbt shows an overview of its model. Click View Model to see the SQL that defines it. The run history graph shows the model's execution time for the period selected on the assets page, and you can filter runs by status: success, error, or skipped. The Test Runs tab shows the dbt tests defined for the model and their run history.
On job pages
Each dbt job has its own asset page with these tabs:
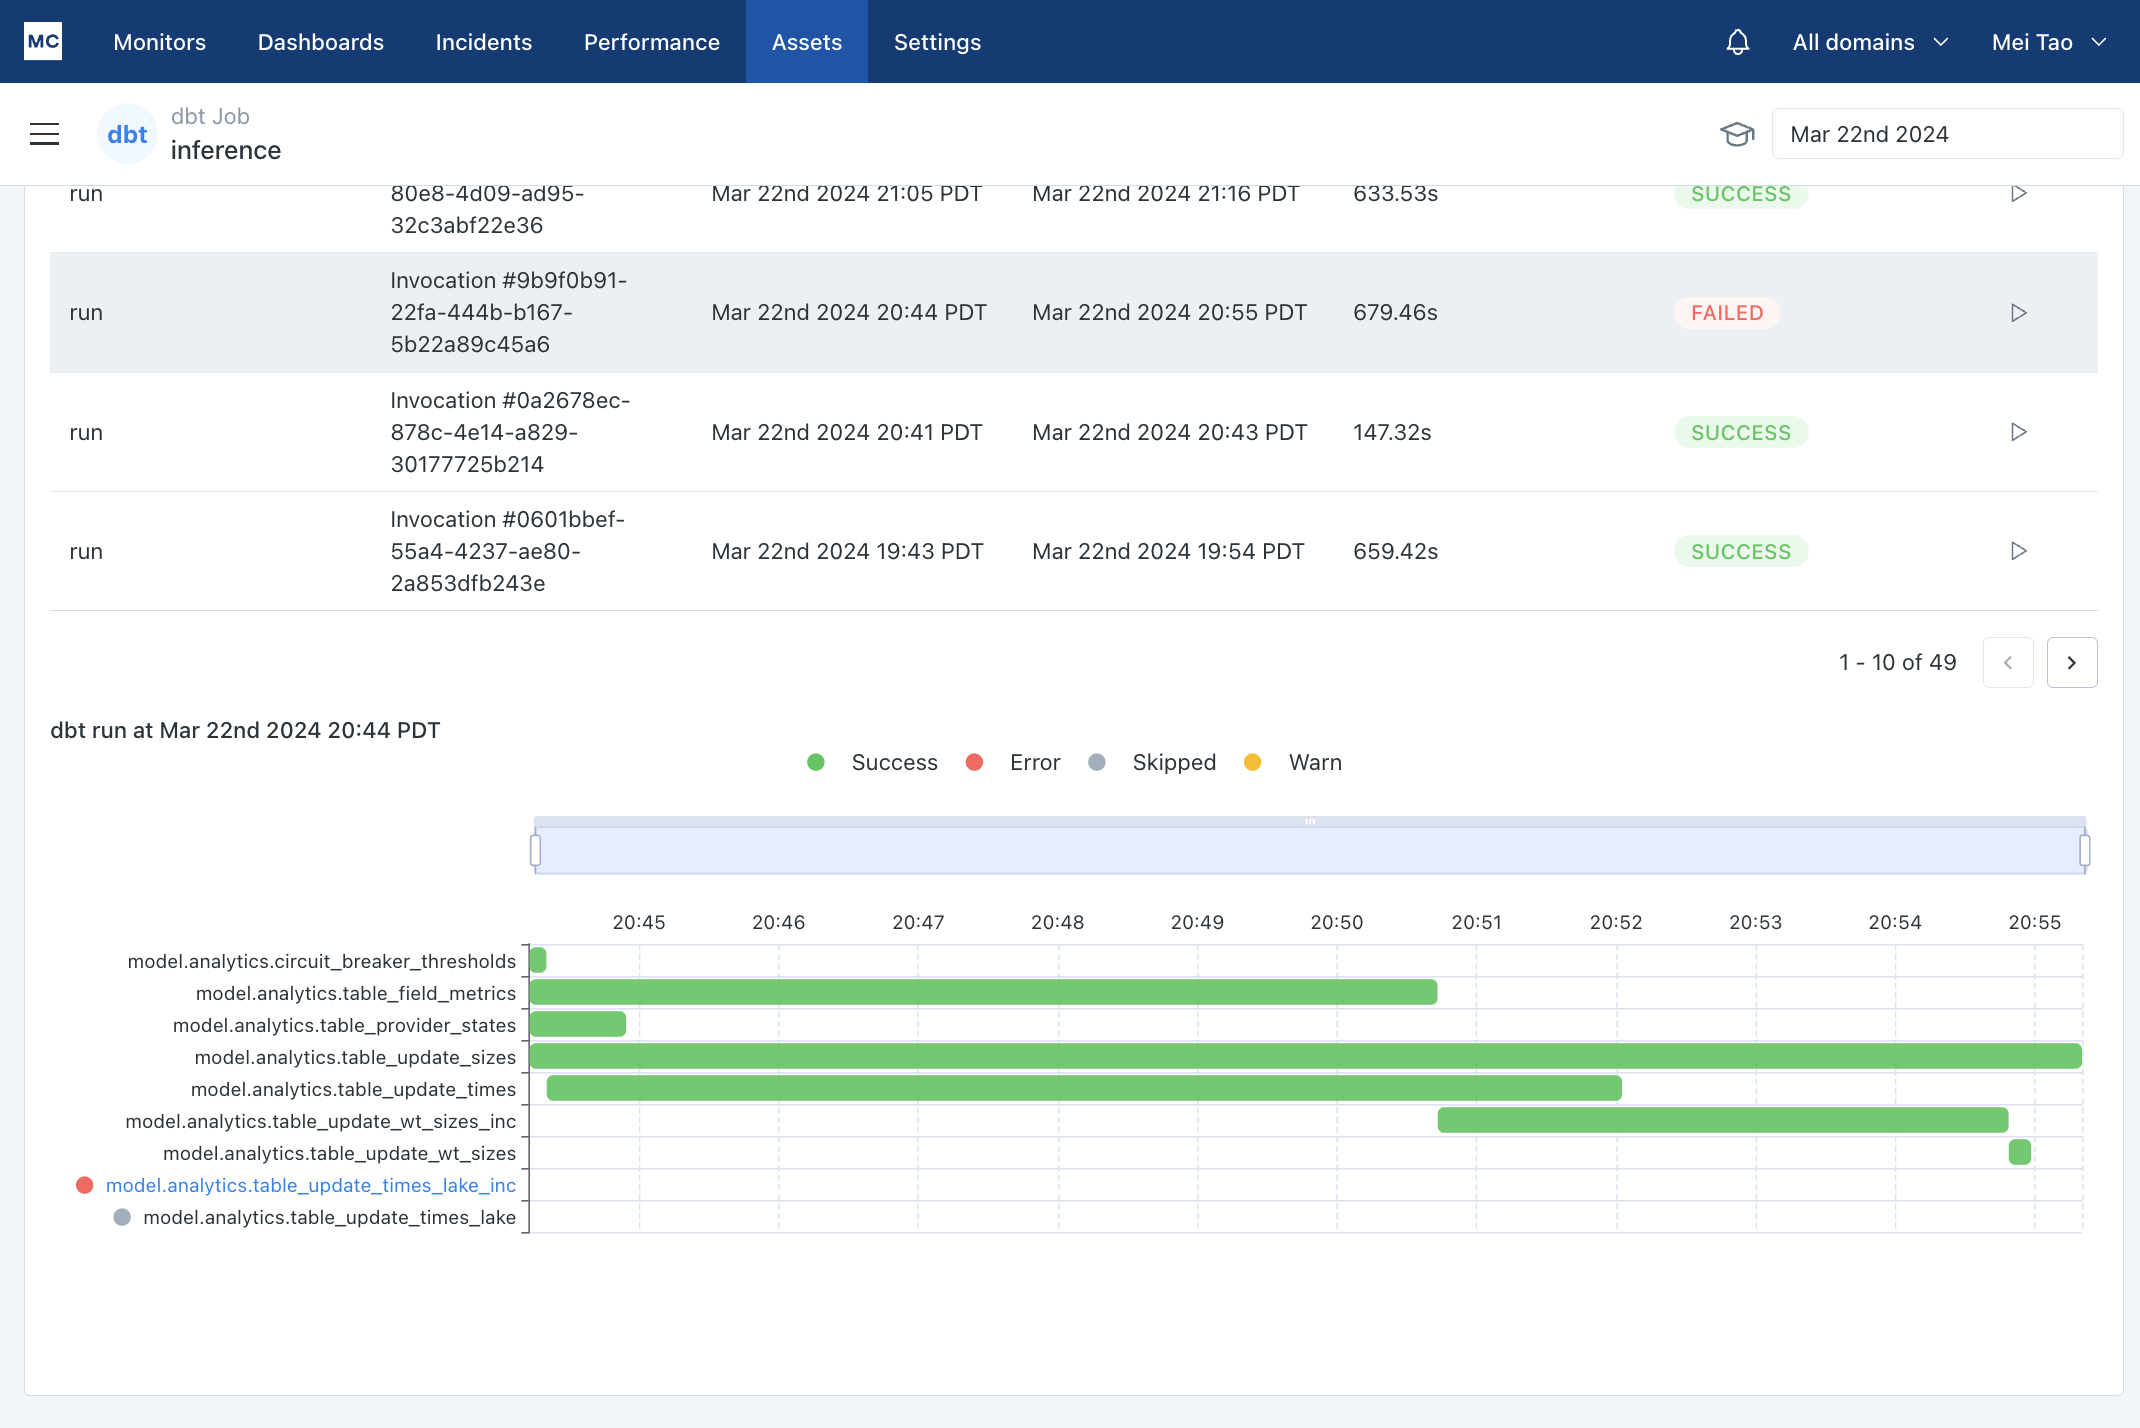
- Runs: each run of the job, with a waterfall (Gantt) view of its models so you can spot bottlenecks
- Models: the models the job runs
- Alerts: alerts raised from the job's failures
- About: the job's details
Setup
- dbt Cloud: create a webhook in dbt Cloud and add the integration in Monte Carlo. See dbt Cloud.
- dbt Core: run the Monte Carlo CLI after each
dbt build,dbt run, ordbt testin your production workflow. See dbt Core. You can also use pycarlo or the dbt operators in airflow-mcd.
Optionally, add a query comment macro to your dbt project to unlock query performance features. See query tagging for dbt Cloud or for dbt Core.
Confirm data is flowing
dbt jobs and models appear in Monte Carlo after a job runs:
- Run a dbt job in production.
- In Monte Carlo, navigate to Assets and search for the job's name, or for a table one of its models builds.
- Verify you can see the run and its model results.
If nothing appears, see the FAQs or ask Bayes.
Failure Alerts
dbt raises five kinds of failure events: Model error, Test failure, Test warning, Snapshot error, and Seed error. A job monitor decides which of them alert and who is notified, and can be limited to failures on certain databases, schemas, or tables. See dbt Failures As Monte Carlo Alerts.
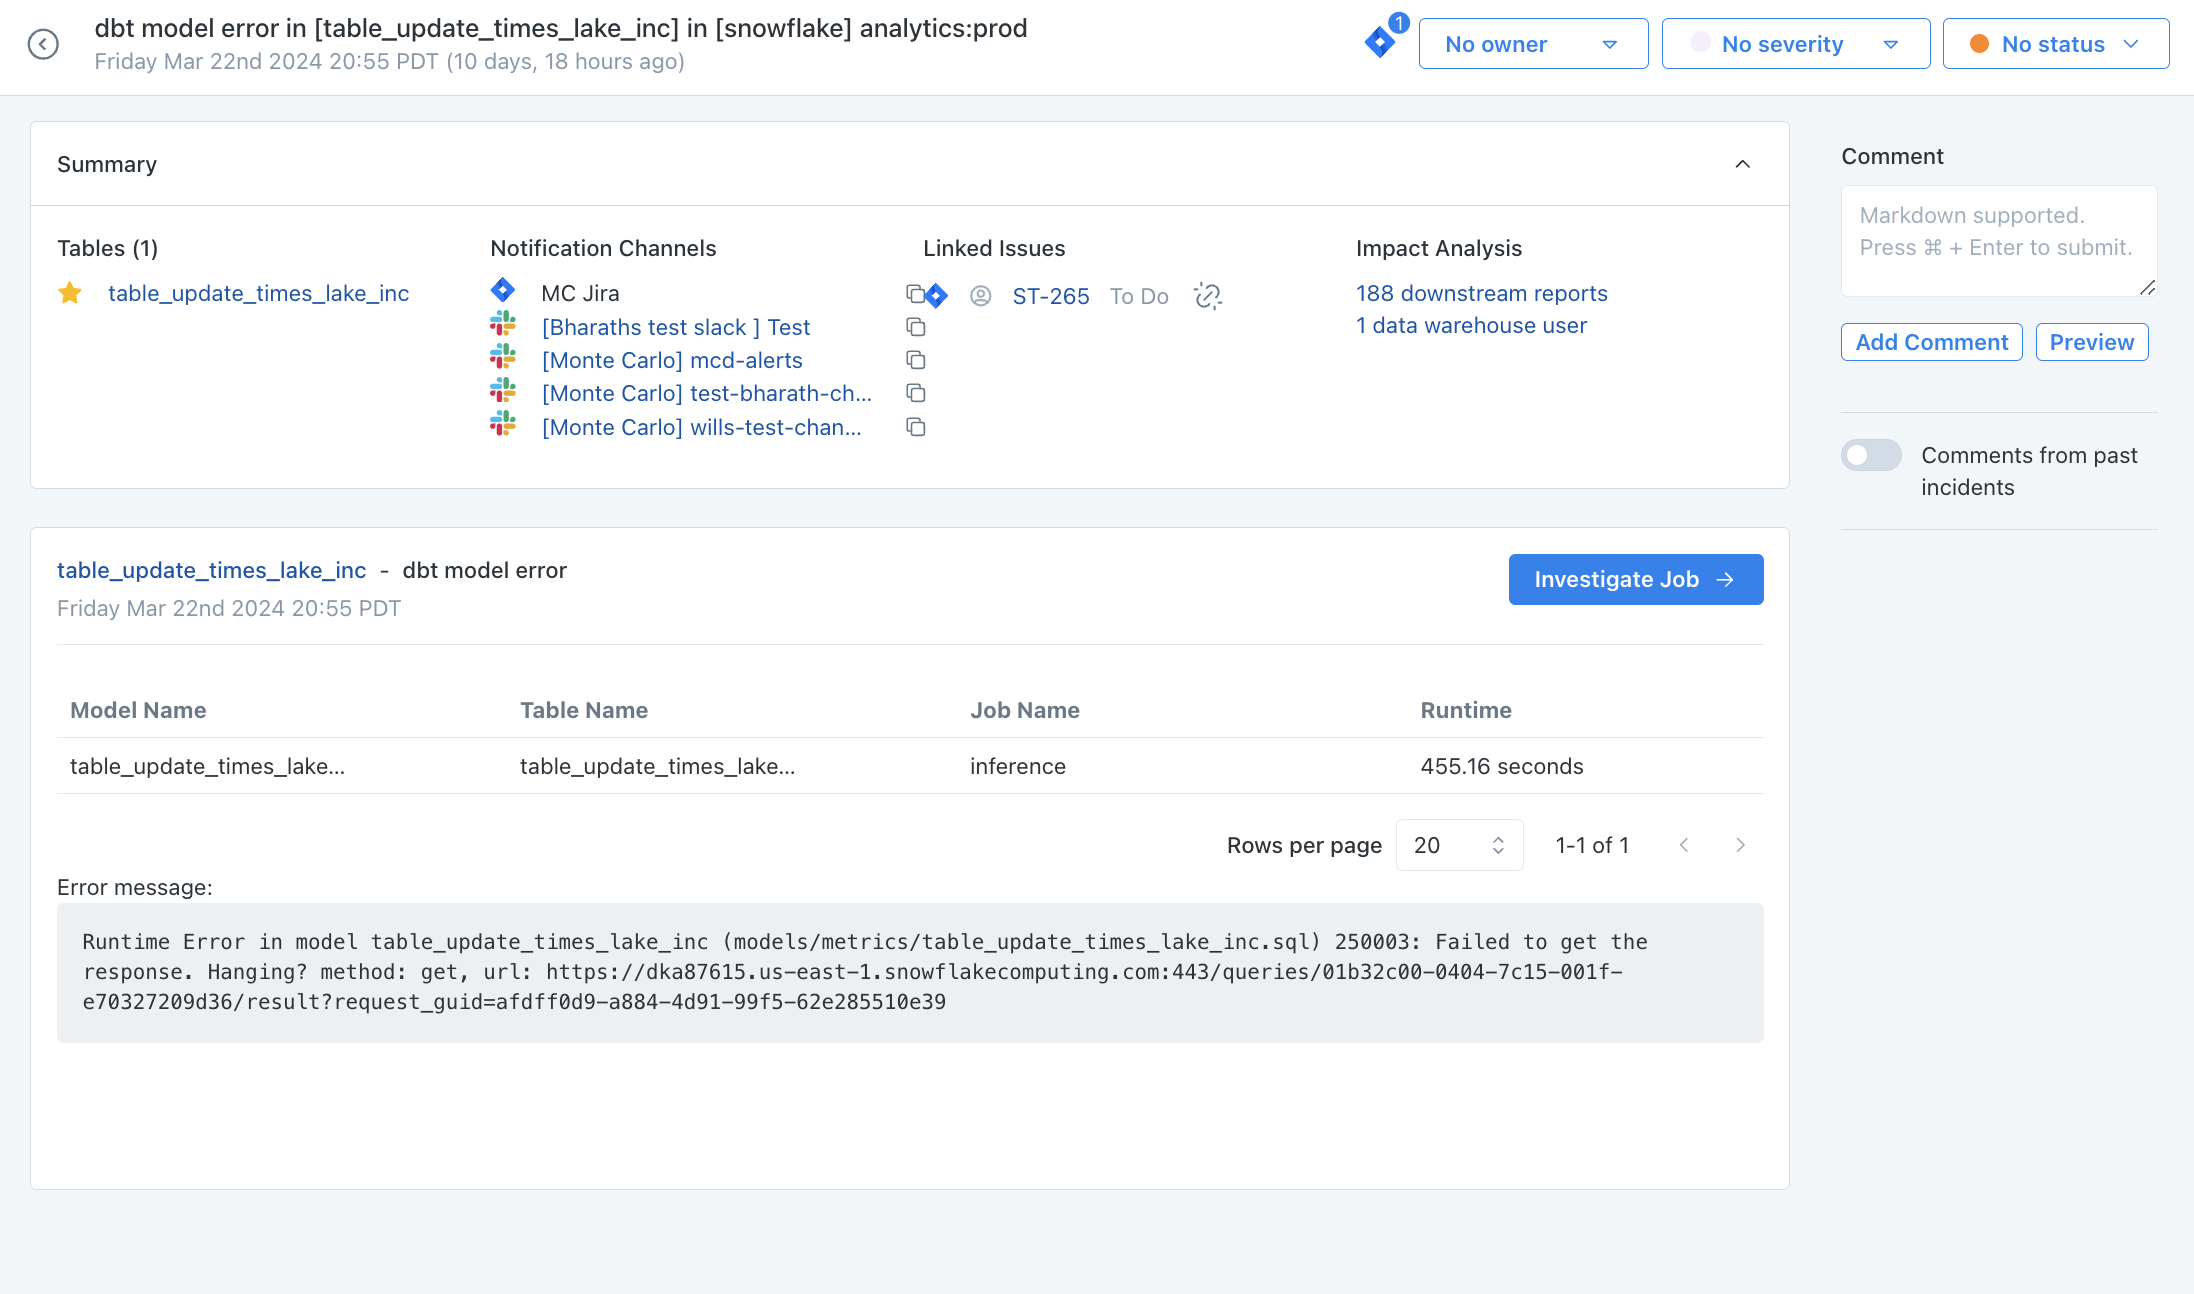
Click Investigate Job on an alert to open the job's run in Assets.
Lineage
Monte Carlo overlays dbt context on your table lineage. Table-to-table lineage itself comes from your warehouse's query logs, not from the dbt manifest.
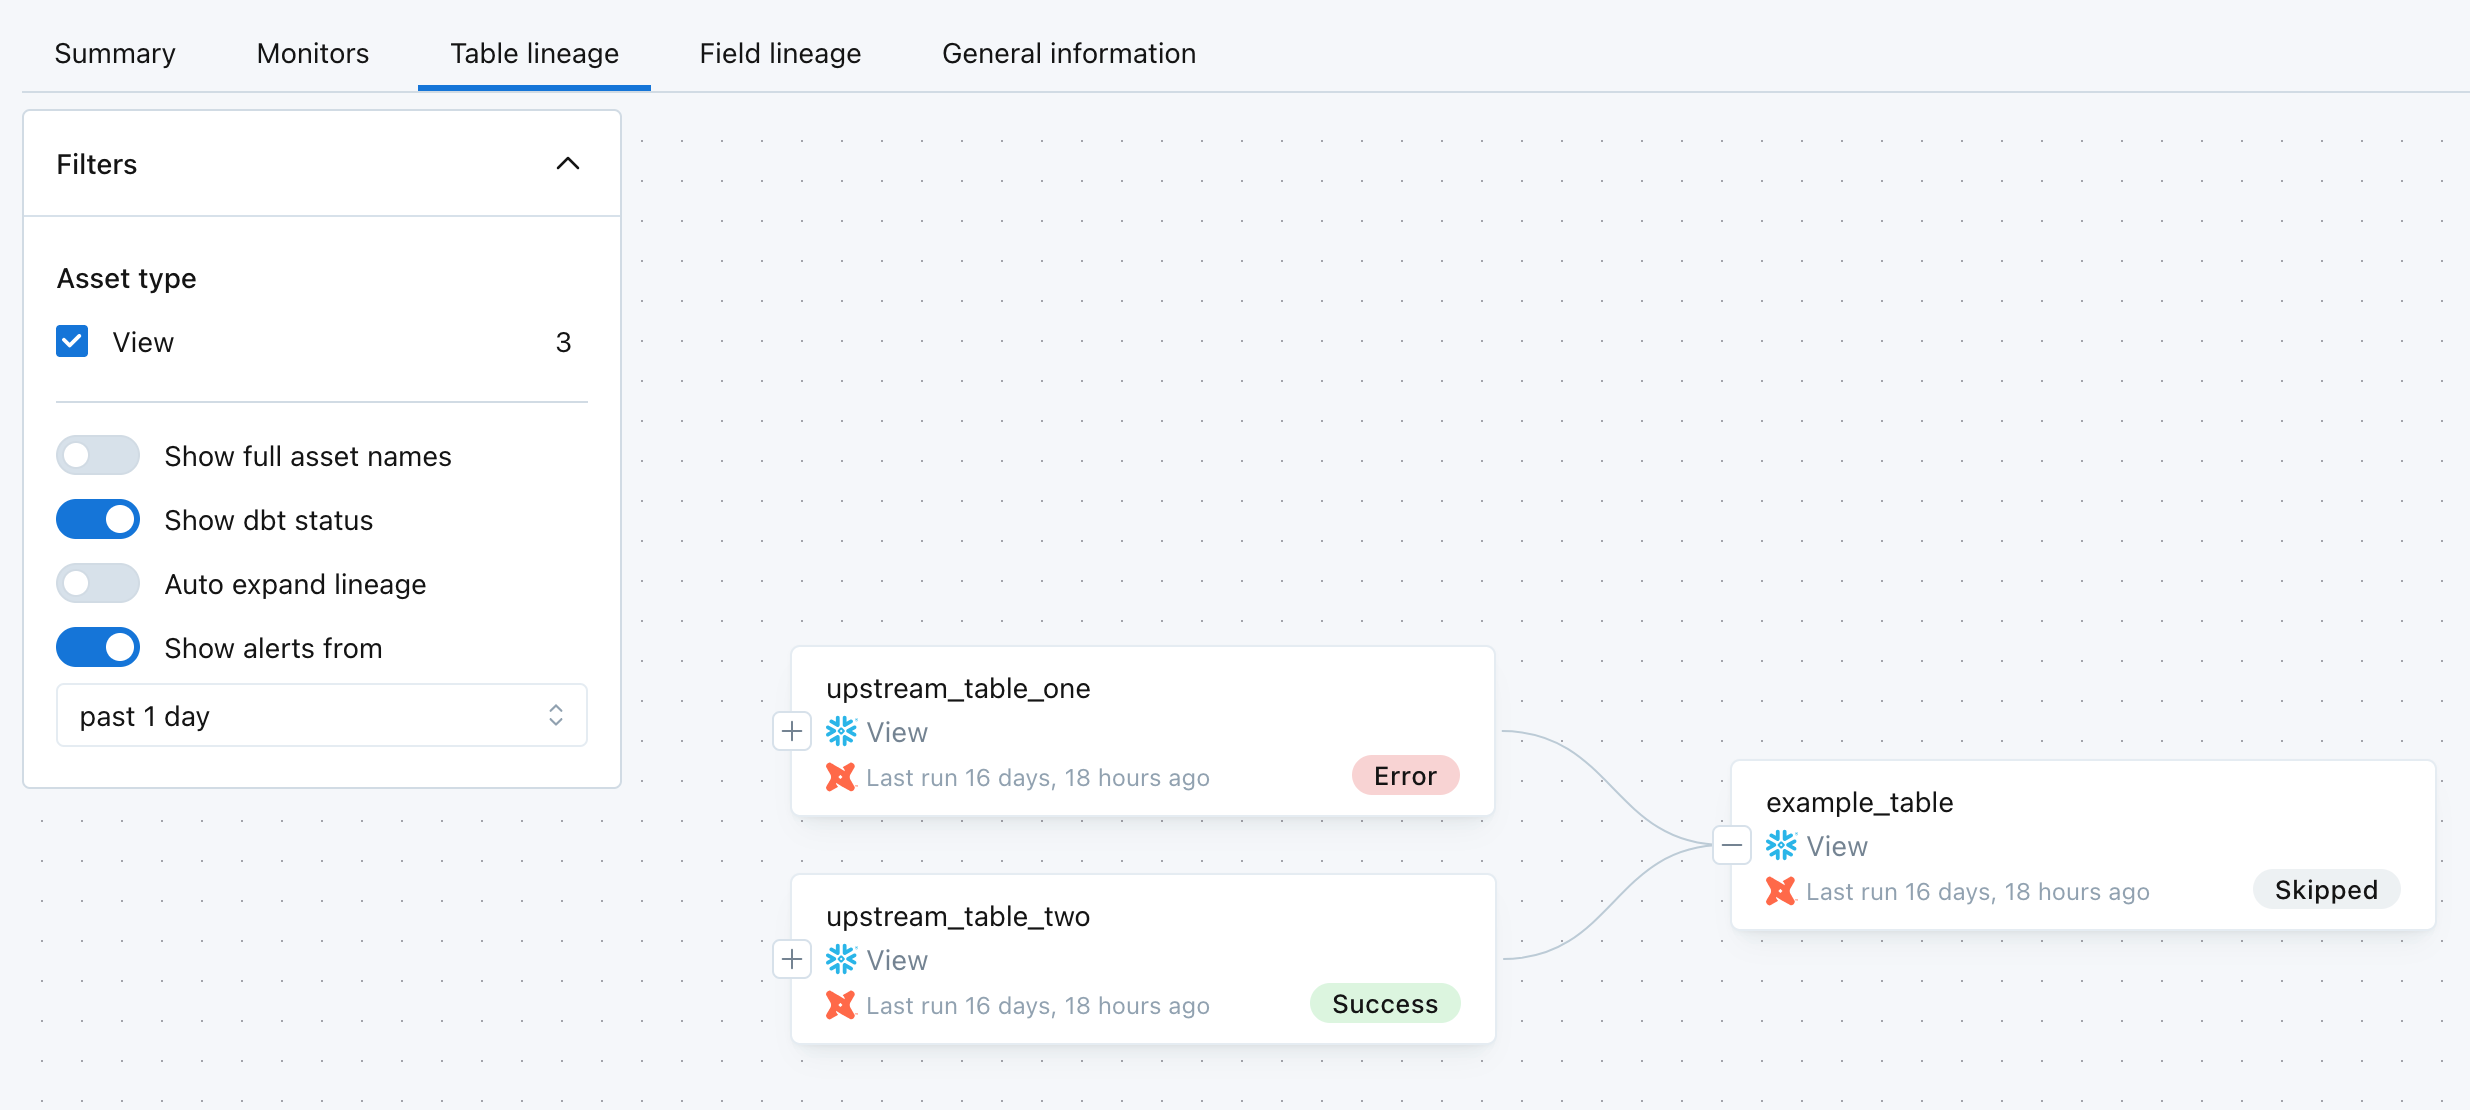
dbt status on lineage nodes
Tables built by dbt show the status of their last dbt run. By default, only Error statuses show on the graph. To see all statuses, turn on Show dbt status in the Filters panel. Click an Error badge to see the related alert.
dbt jobs on lineage edges
When a dbt job reads an upstream table and builds the downstream table, Monte Carlo shows a dbt icon on the edge between them. Hover over it to see the job (or jobs), and click it to see the job's run history and command details.
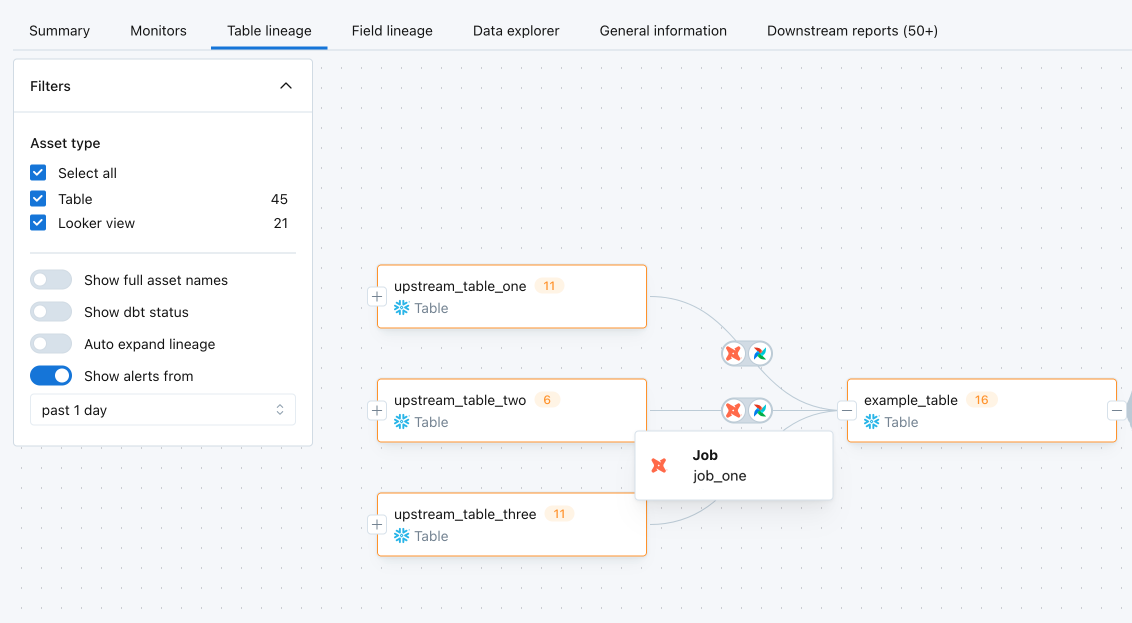
No dbt icon on an edge? The same dbt job must both read the upstream table and build the downstream table's model:
- Source-target relationship: the model must reference the upstream table with
source()orref(). - Same job run: if a job builds only one model (for example,
dbt run --select <model>), the edge may not appear unless the upstream model is also built in the same run.
The dbt status on the node is shown either way.
FAQs
Q: I've run a dbt job but don't see it in Monte Carlo. What should I check?
- dbt Cloud: the webhook isn't set up. Monte Carlo collects dbt Cloud runs only when the webhook fires. See dbt Cloud Webhooks.
- dbt Core: the CLI didn't run after the dbt command. Run
montecarlo import dbt-runafter each dbt command, in the same session. - The models don't match tables in Monte Carlo. Check that the warehouse the job writes to is connected and that its schemas aren't excluded. With more than one warehouse, dbt Core uploads also need
--connection-id.
Q: How long does it take for dbt data to show up?
dbt jobs, runs, and models appear shortly after a run is collected. dbt context in lineage can take up to 24 hours due to batch processing.
Q: Why don't I see a dbt job in the job monitor picker or on the Assets page?
The job monitor picker lists dbt jobs that ran in the last 7 days. The jobs list on the Assets page shows jobs that ran in the selected time period. A job reappears once it runs again.
Q: What is the largest manifest.json Monte Carlo can process?
300 MB, which covers the vast majority of dbt jobs. If you need a larger manifest processed, ask Bayes and we can evaluate your use case.
Q: On the Jobs Performance page, why does my "default-job" dbt job take a long time to load?
"default-job" is the job name Monte Carlo assigns to dbt Core runs when no job name is given. All runs land in one job that usually includes hundreds of models, tests, snapshots, and seeds, which makes performance metrics slow to calculate. Split it into smaller jobs by giving each dbt command a unique job name.
Q: I'm getting a CA certificate error when running the Monte Carlo CLI for dbt.
CA certificate errors come from the local execution environment, such as missing, expired, or misconfigured root or intermediate certificates in the OS or Python trust store. The CLI relies on the system's certificate chain for TLS verification and doesn't manage certificates. Update the local environment to resolve them.
Updated 6 days ago