
Redshift
What is Redshift?
Amazon Redshift is a fully managed, petabyte-scale data warehouse service in the cloud. Amazon Redshift Serverless lets you access and analyze data without all of the configurations of a provisioned data warehouse.
Why Connect Redshift to Monte Carlo?
Connecting your Redshift account to Monte Carlo, and giving us access to the data within is essential for Monte Carlo to function. Monte Carlo needs to be able to collect the metadata of your tables in Redshift to enable our Freshness and Volume Table monitors. With access to the query logs of those tables, we will be able to build table and field lineage. With the ability to run SQL queries on those tables, Monte Carlo can run advanced monitors to analyze the data in those tables.
Your agents and analytics depend on this data, so the biggest step in getting value from Monte Carlo is letting it observe your data!
After connecting Redshift here is what you can expect to see:
Freshness and Volume:
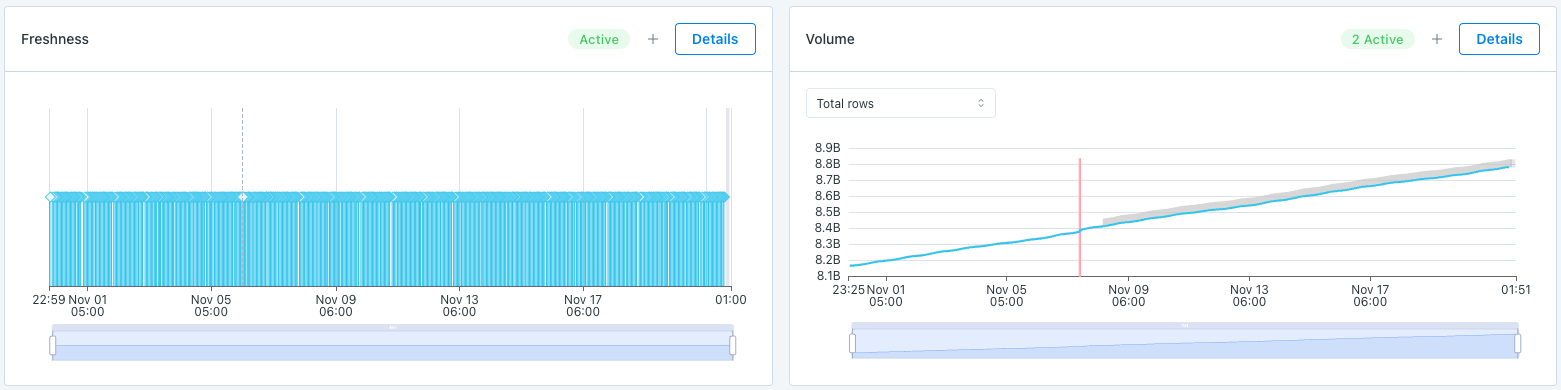
Freshness and volume are monitored by a Table monitor. Connecting the integration doesn't monitor any tables on its own: create a Table monitor and choose the databases and schemas it covers. By collecting metadata on your tables, Monte Carlo’s machine learning algorithm can set automatic thresholds to alert when a table has gone too long without an update, and when an abnormal amount of rows are added or deleted.
Query Logs:
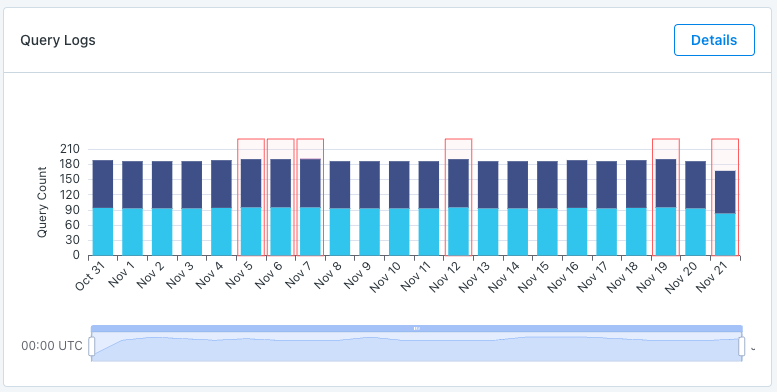
When giving access to query logs Monte Carlo is able to show the amount of read and write queries on a table, and give you access to the details of those queries. Monte Carlo can even highlight when a query appears to have failed.
Table Lineage:
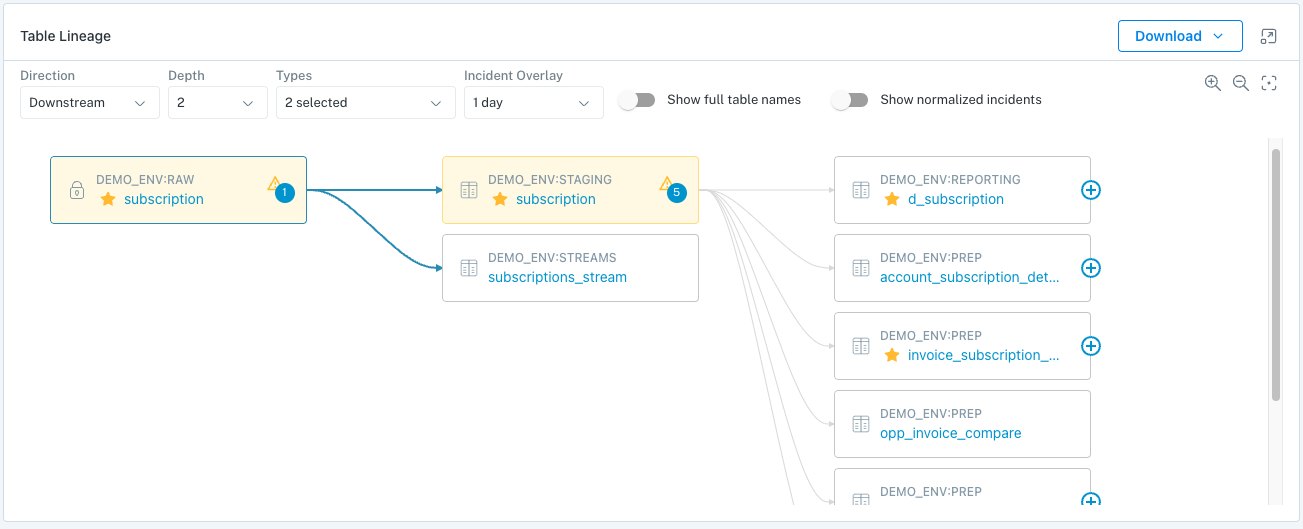
Monte Carlo is able to map the connections between your tables, and can show upstream and downstream connections. We can even connect anomalies that are detected in upstream tables to anomalies in downstream tables.
To review all steps necessary to integrate a data warehouse with Monte Carlo, please see here.
Monitor & Lineage Support
Below are the monitors and lineage support for the Redshift integration today. Please reach out to your Monte Carlo representative if you have requirements for additional monitors.
| Category | Monitor / Lineage Capabilities | Support |
|---|---|---|
| Table Monitor | Freshness | ✅ |
| Table Monitor | Volume | ✅ |
| Table Monitor | Schema Changes | ✅ |
| Metric Monitor | Metric | ✅ |
| Metric Monitor | Comparison | ✅ |
| Validation Monitor | Custom SQL | ✅ |
| Validation Monitor | Validation | ✅ |
| Job Monitor | Query performance | ✅ |
| Lineage | Lineage | ✅ |
Connect end to end with Claude or TerraformWant a guided setup? With the Monte Carlo Agent Toolkit, run the following command and Claude walks you through every step:
/monte-carlo-onboarding connect RedshiftSee Providing credentials with Claude for details.
Want it all as code? With the Monte Carlo Terraform provider, one
terraform applycreates the credentials, warehouse and connection. See Providing credentials with the Terraform provider or themontecarlo_redshift_credentialsresource in the registry.Prefer the UI? Create the service account below, then provide its credentials in the onboarding wizard.
Creating a service account
Admin credentials requiredTo make the read only service user for Monte Carlo, you will need admin credentials to your Redshift cluster.
Please use the following SQL snippet to create a service account for Monte Carlo:
CREATE USER <username> PASSWORD ‘<password>’ SYSLOG ACCESS UNRESTRICTED
GRANT SELECT ON svv_table_info to <username>
GRANT SELECT ON ALL TABLES IN SCHEMA <schema_name> [, …] to <username>
GRANT USAGE ON SCHEMA <schema_name> [, …] to <username>
GRANT USAGE ON SCHEMA <external_schema> [, …] to <username>
ALTER DEFAULT PRIVILEGES FOR USER <user_creating_tables> [, …] IN SCHEMA <schema_name> [, …] GRANT SELECT ON TABLES TO <username>
Before using the snippet, you will need to populate the following:
- <username>: Service account username, typically "monte_carlo".
- <password>: Strong password to be used by the service account user.
- <schema_name>: Redshift schema(s) to be monitored. Please note you can provide a list of schemas in a single statement.
- <external_schema>: Redshift Spectrum schema(s) – where external tables are defined – to be monitored. Please note you can provide a list of schemas in a single statement.
- <user_creating_tables>: Redshift user(s) that create/update tables and external tables, typically the user(s) used by your ETL jobs. Please note you can provide a list of such users in a single statement.
Please note:
- syslog permissions allow Monte Carlo to to read query logs from all users.
- select permissions on svv_table_info allow Monte Carlo to to read metadata about tables in your warehouse.
- select and usage permissions on schemas allow Monte Carlo to track health for tables in the given schemas.
- usage permissions on external schemas allow Monte Carlo to to track health for external tables in the given schemas.
- Default privileges set for ETL users make sure that Monte Carlo maintains access to tables as ETL jobs run and update/create tables.
For control over which assets are ingested and monitored, use Usage controls.
Providing credentials with the Terraform provider
The Terraform provider is in beta. It is versioned
0.x, so pin its minor version.
The Terraform provider takes the same details as the wizard. montecarlo_redshift_credentials holds the host, port, database, user and password, and montecarlo_warehouse and montecarlo_connection put them on a deployment:
resource "montecarlo_warehouse" "redshift" {
  name          = "production-redshift"
  type          = "redshift"
  deployment_id = var.deployment_id
}

resource "montecarlo_redshift_credentials" "redshift" {
  host                = "examplecluster.abc123xyz789.us-east-1.redshift.amazonaws.com"
  port                = 5439
  db_name             = "analytics"
  user                = "monte_carlo"
  password_wo         = var.redshift_password
  password_wo_version = 1
}

resource "montecarlo_connection" "redshift" {
  name           = "production-redshift"
  warehouse_id   = montecarlo_warehouse.redshift.id
  credentials_id = montecarlo_redshift_credentials.redshift.id
}
deployment_id is the deployment the connection runs on: your collection agent's, or the Cloud deployment under Settings > Deployments if Monte Carlo connects from its cloud. Keep secrets in variables set from an uncommitted *.tfvars file or the environment; write-only arguments keep them out of the Terraform state and plan, which needs Terraform 1.11 or later. See montecarlo_redshift_credentials in the registry for every argument, including the SSL options.
Providing credentials with Claude
With the Agent Toolkit, run /monte-carlo-onboarding connect Redshift and Claude does the Monte Carlo steps through the MCP server. The password never passes through the chat: Claude gives you the command or the Terraform, and you run it on your machine. Pick the example closest to your setup:
- Connect Redshift from the Monte Carlo cloud: no agent; Monte Carlo connects from its cloud.
- Connect Redshift through a collection agent: the agent runs in your AWS account.
[Optional] Connect using SSL
Monte Carlo supports connecting to your Redshift cluster over an SSL/TLS-encrypted connection and verifying the server's identity against a CA certificate you provide. This is configured in the connection form when you add or edit a Redshift integration — no change to the connection port is required.
Minimum agent versionIf your Redshift connection is served through a containerized agent, SSL requires agent version 2074 or later. Older agents fail the connection test with a clear upgrade prompt rather than silently connecting without SSL. Connections that don't use a containerized agent have no minimum-version requirement.
In the Redshift connection form, expand Advanced — SSL options:
- CA certificate (PEM) — upload a PEM-formatted CA certificate to verify the Redshift server. Monte Carlo uses it to validate the server's certificate when establishing the connection.
- Verify server identity — with a CA certificate uploaded, leave this on to also require that the server certificate's hostname matches the cluster you're connecting to. Turn it off to validate the certificate chain only (for example, when the certificate is issued to a different name).
- Disable SSL — explicitly connect without TLS.
Leaving these options blank connects using the server's default behavior.
Editing an existing connectionFor security, an uploaded CA certificate is never shown after saving. Your existing SSL settings stay in effect when you edit a connection and aren't changed unless you upload a CA certificate again or turn on Disable SSL.
Configure SSL with the CLI
CA-only SSL is also available when you add a Redshift connection with the Monte Carlo CLI. The integrations add-redshift command accepts:
--ssl-ca <path>— path to a file containing a PEM-formatted CA certificate. The Redshift server's certificate is verified against it when the connection is tested and added.--ssl-disabled— connect without TLS.
montecarlo integrations add-redshift --ssl-ca /path/to/ca.pem [other options...]Run montecarlo integrations add-redshift --help for the full option list. The CLI covers the CA certificate and disable options; the Verify server identity toggle is available in the connection form only. These flags apply when adding a connection — to change SSL on an existing connection, edit it in the connection form.
Configure SSL with the Terraform provider
montecarlo_redshift_credentials covers every SSL option in the connection form, including Verify server identity:
ssl_ca_data: PEM text of the CA certificate, for examplefile("${path.module}/ca.pem").ssl_verify_identity: also require that the certificate names the host.ssl_disabled: connect without TLS.
FAQs
Can I monitor all databases in my deployment?
Yes, this feature is now in public preview. Ask Bayes if you would like this feature enabled for your integration.
Why am I missing views in Monte Carlo?
If you are using late binding views in your pipeline, please note that Monte Carlo will not pull in these views by default, meaning they will be unavailable to set advanced monitors on. Since these views only exist at the moment they are referenced, there is no data to collect from the cluster's system level views during our hourly collections. You can tell you are using a late binding view if the statement with no schema binding exists in the view definition. Please see the Redshift documentation for more information.
If setting monitors on these views is important to you, Monte Carlo does have the ability to ingest them! However, the way we collect these views is slightly different than the way we collect the rest of the cluster metadata due to the aforementioned reasoning, and so one side effect of enabling this on your collection jobs is catalog bloat. Historically, when we have enabled this type of collection for users, we have seen the amount of cluster resources we had to use to collect metadata increase.
If you are interested in this functionality or want to learn more about your options, please reach out to your Monte Carlo representative or ask Bayes for more information.
How can I validate Monte Carlo has access to my assets?
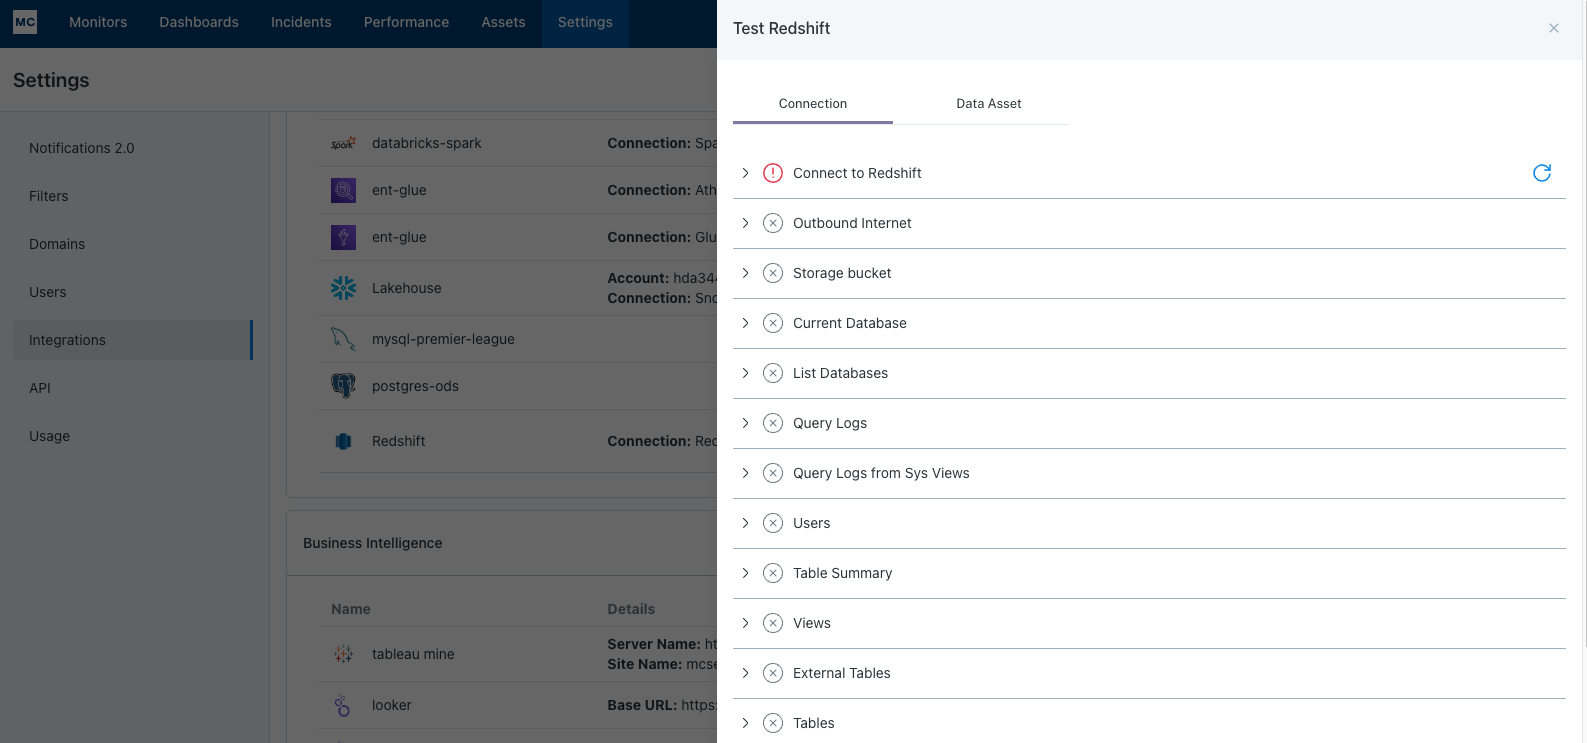
After completing the Redshift integration setup, your Redshift assets should appear in the Monte Carlo Assets page between a few minutes and one hour. If you don't see your assets after this time period, you can run a validation test to troubleshoot the connection:
- Navigate to Settings → Integrations
- Find your Redshift integration and click on it
- Select the specific connection you want to test
- Click the Test button from the connection menu
This validation test will help identify any configuration issues that might be preventing your assets from appearing.
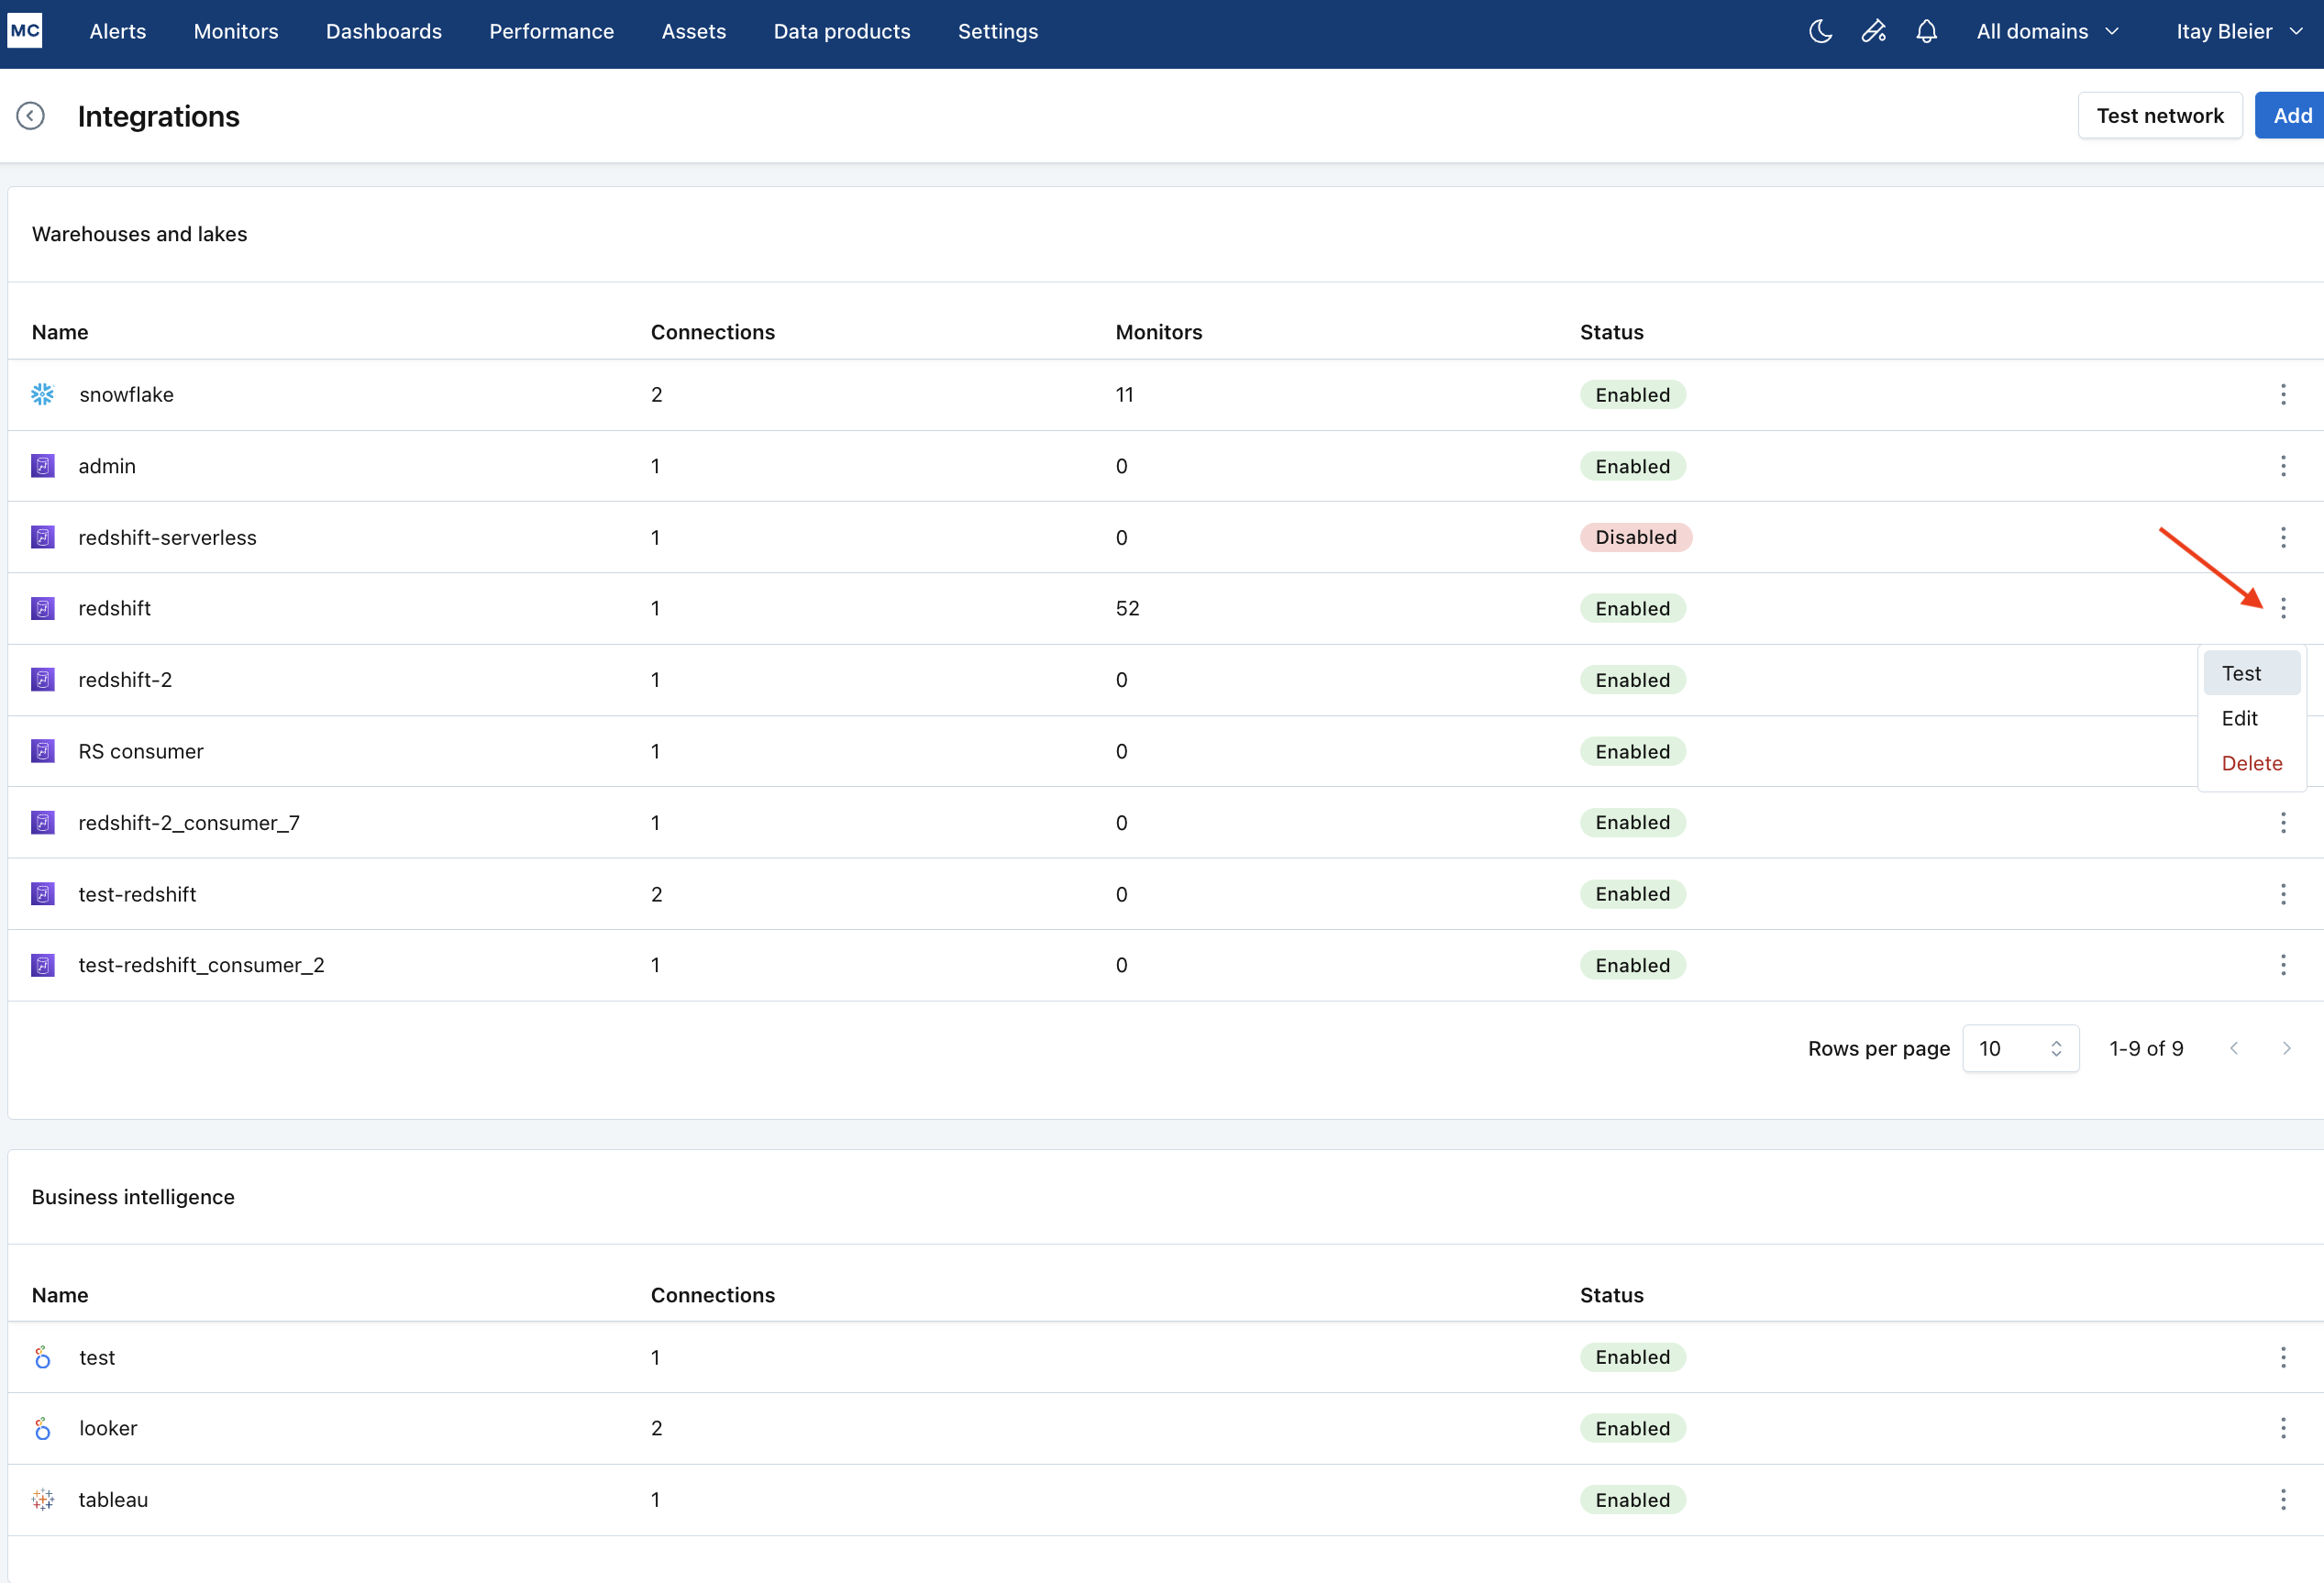
When running the validation test, you should see all green checkmarks. If any errors are encountered, the system will provide specific steps to resolve them.
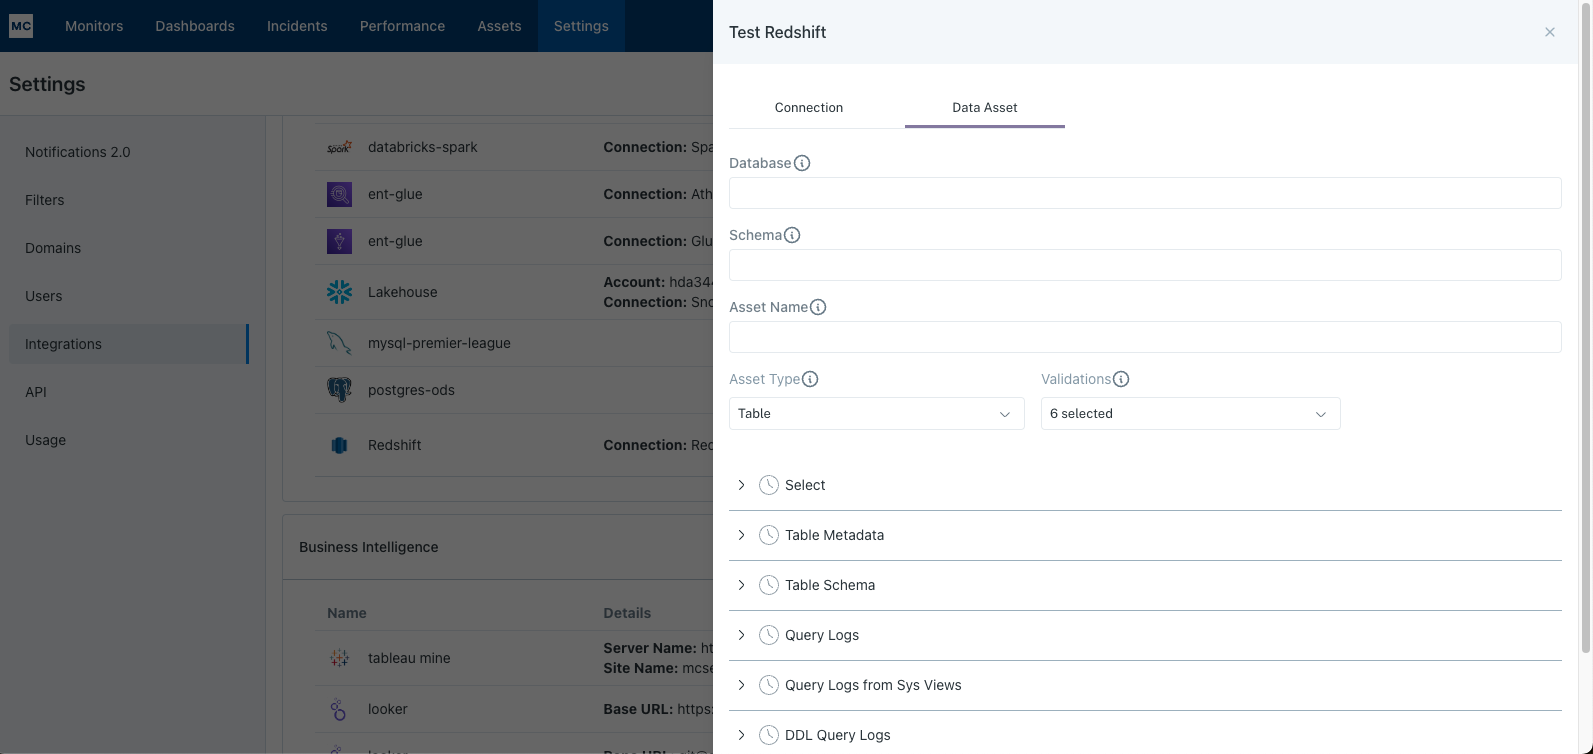
If assets from a specific database or schema are missing you can use the Data Asset validation to test our ability to access them:
Note: Lineage can take up to 24 hours due to batching.
Where can the dbt comment go in a Redshift query?
At the start or the end of the query. Monte Carlo reads the comment wherever it appears.
Details and edge cases
Which Redshift objects Monte Carlo reads. Monte Carlo reads system views, not SHOW commands: svv_redshift_databases, svv_all_schemas, svv_tables, svv_table_info, pg_views and svv_columns for metadata, svv_all_tables and svv_all_columns for datashare tables, svv_external_tables for external tables, and stl_query, stl_querytext and stl_ddltext for query logs (sys_query_history and sys_query_text on Redshift Serverless), with pg_user for user names.
Updated 3 days ago